Overview
New image and video models ship every few weeks, each promising better quality. For licensed products, better has a narrow meaning: the logo, the numbers, the material and the color have to match the licensed art exactly. The team needed one consistent way to tell whether a new model or platform actually moves production forward.
New models, same test
Every model that ships, whether Nano Banana, Seedream, Image 2.0, Wan or whatever comes next, runs through the same framework, so improvements are measured rather than assumed.
Different platforms, same bar
Each platform's own generative tooling, such as Figma Weave and Flora, is judged on the same quality bar, not just the model underneath.
Test Method
The same four steps apply to every test case. The first two are built once; for each new model, only the last two run again.
- 1Gold ShotA real, physically shot photo: the answer key everything is measured against.
- 2Standard inputFixed reference images and one locked prompt, never rewritten mid-test.
- 3Benchmark runEvery model or platform gets the same inputs, with no adjustments mid-run.
- 4Score & compareEach output is scored on the criteria, side by side with the Gold Shot.
Six Test Cases
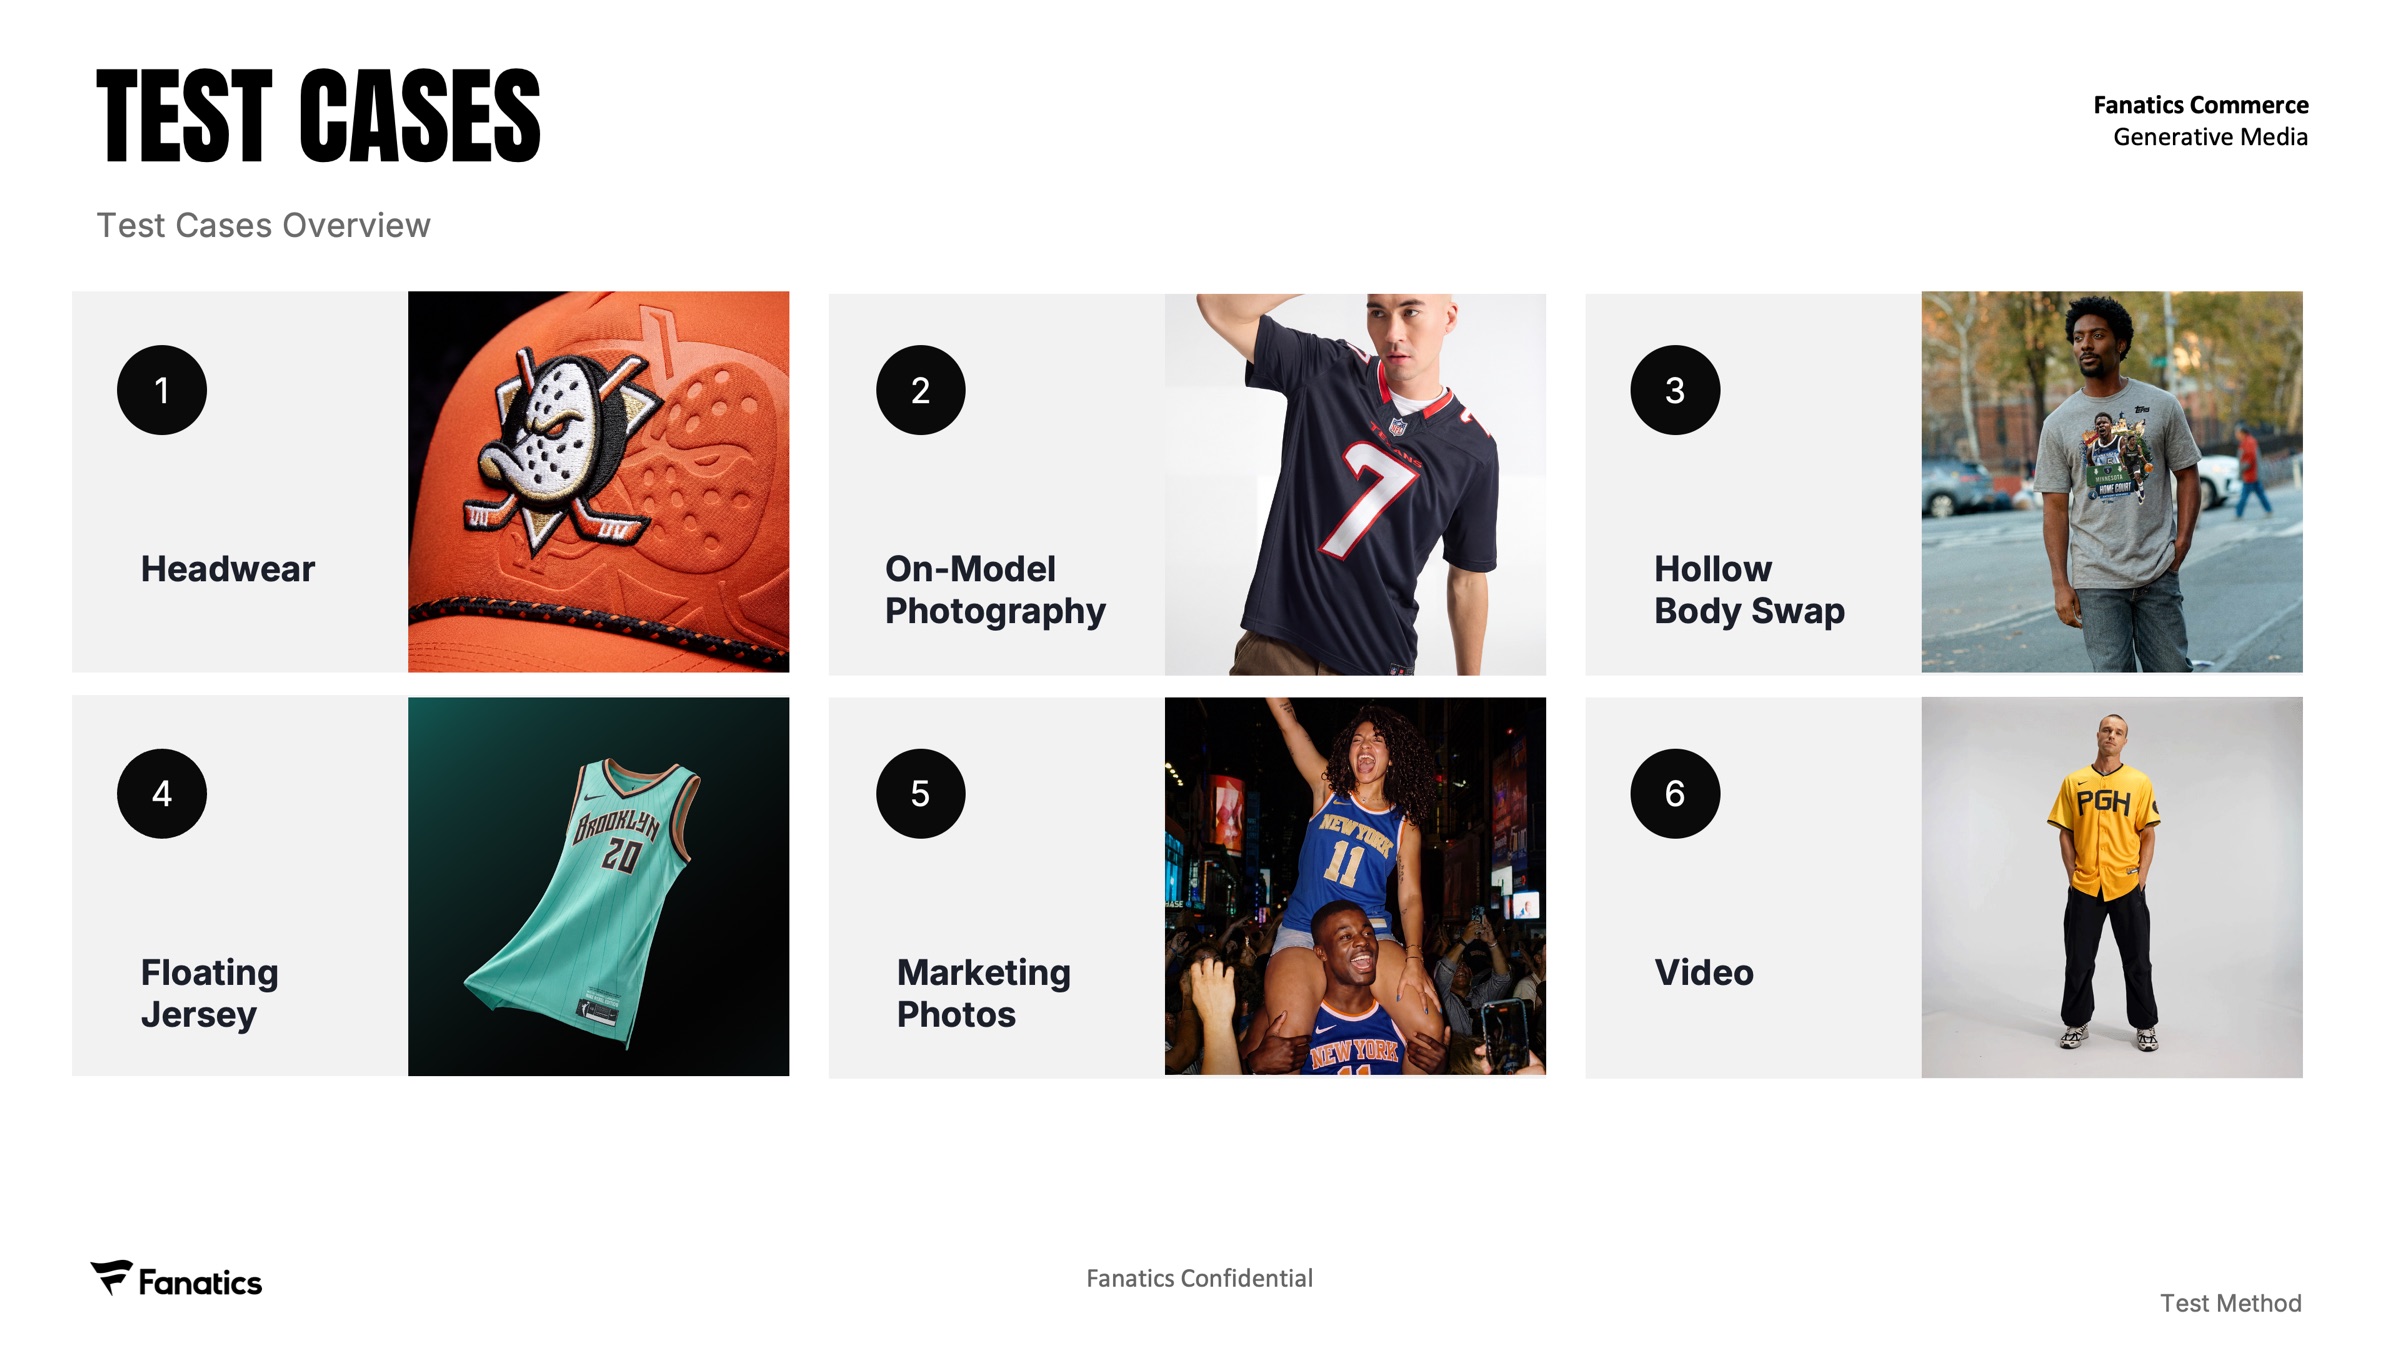
The cases cover the work the team ships most: headwear macro shots, on-model photography, hollow-body swaps, floating jerseys, multi-step marketing images and on-model video.
Evaluation Criteria
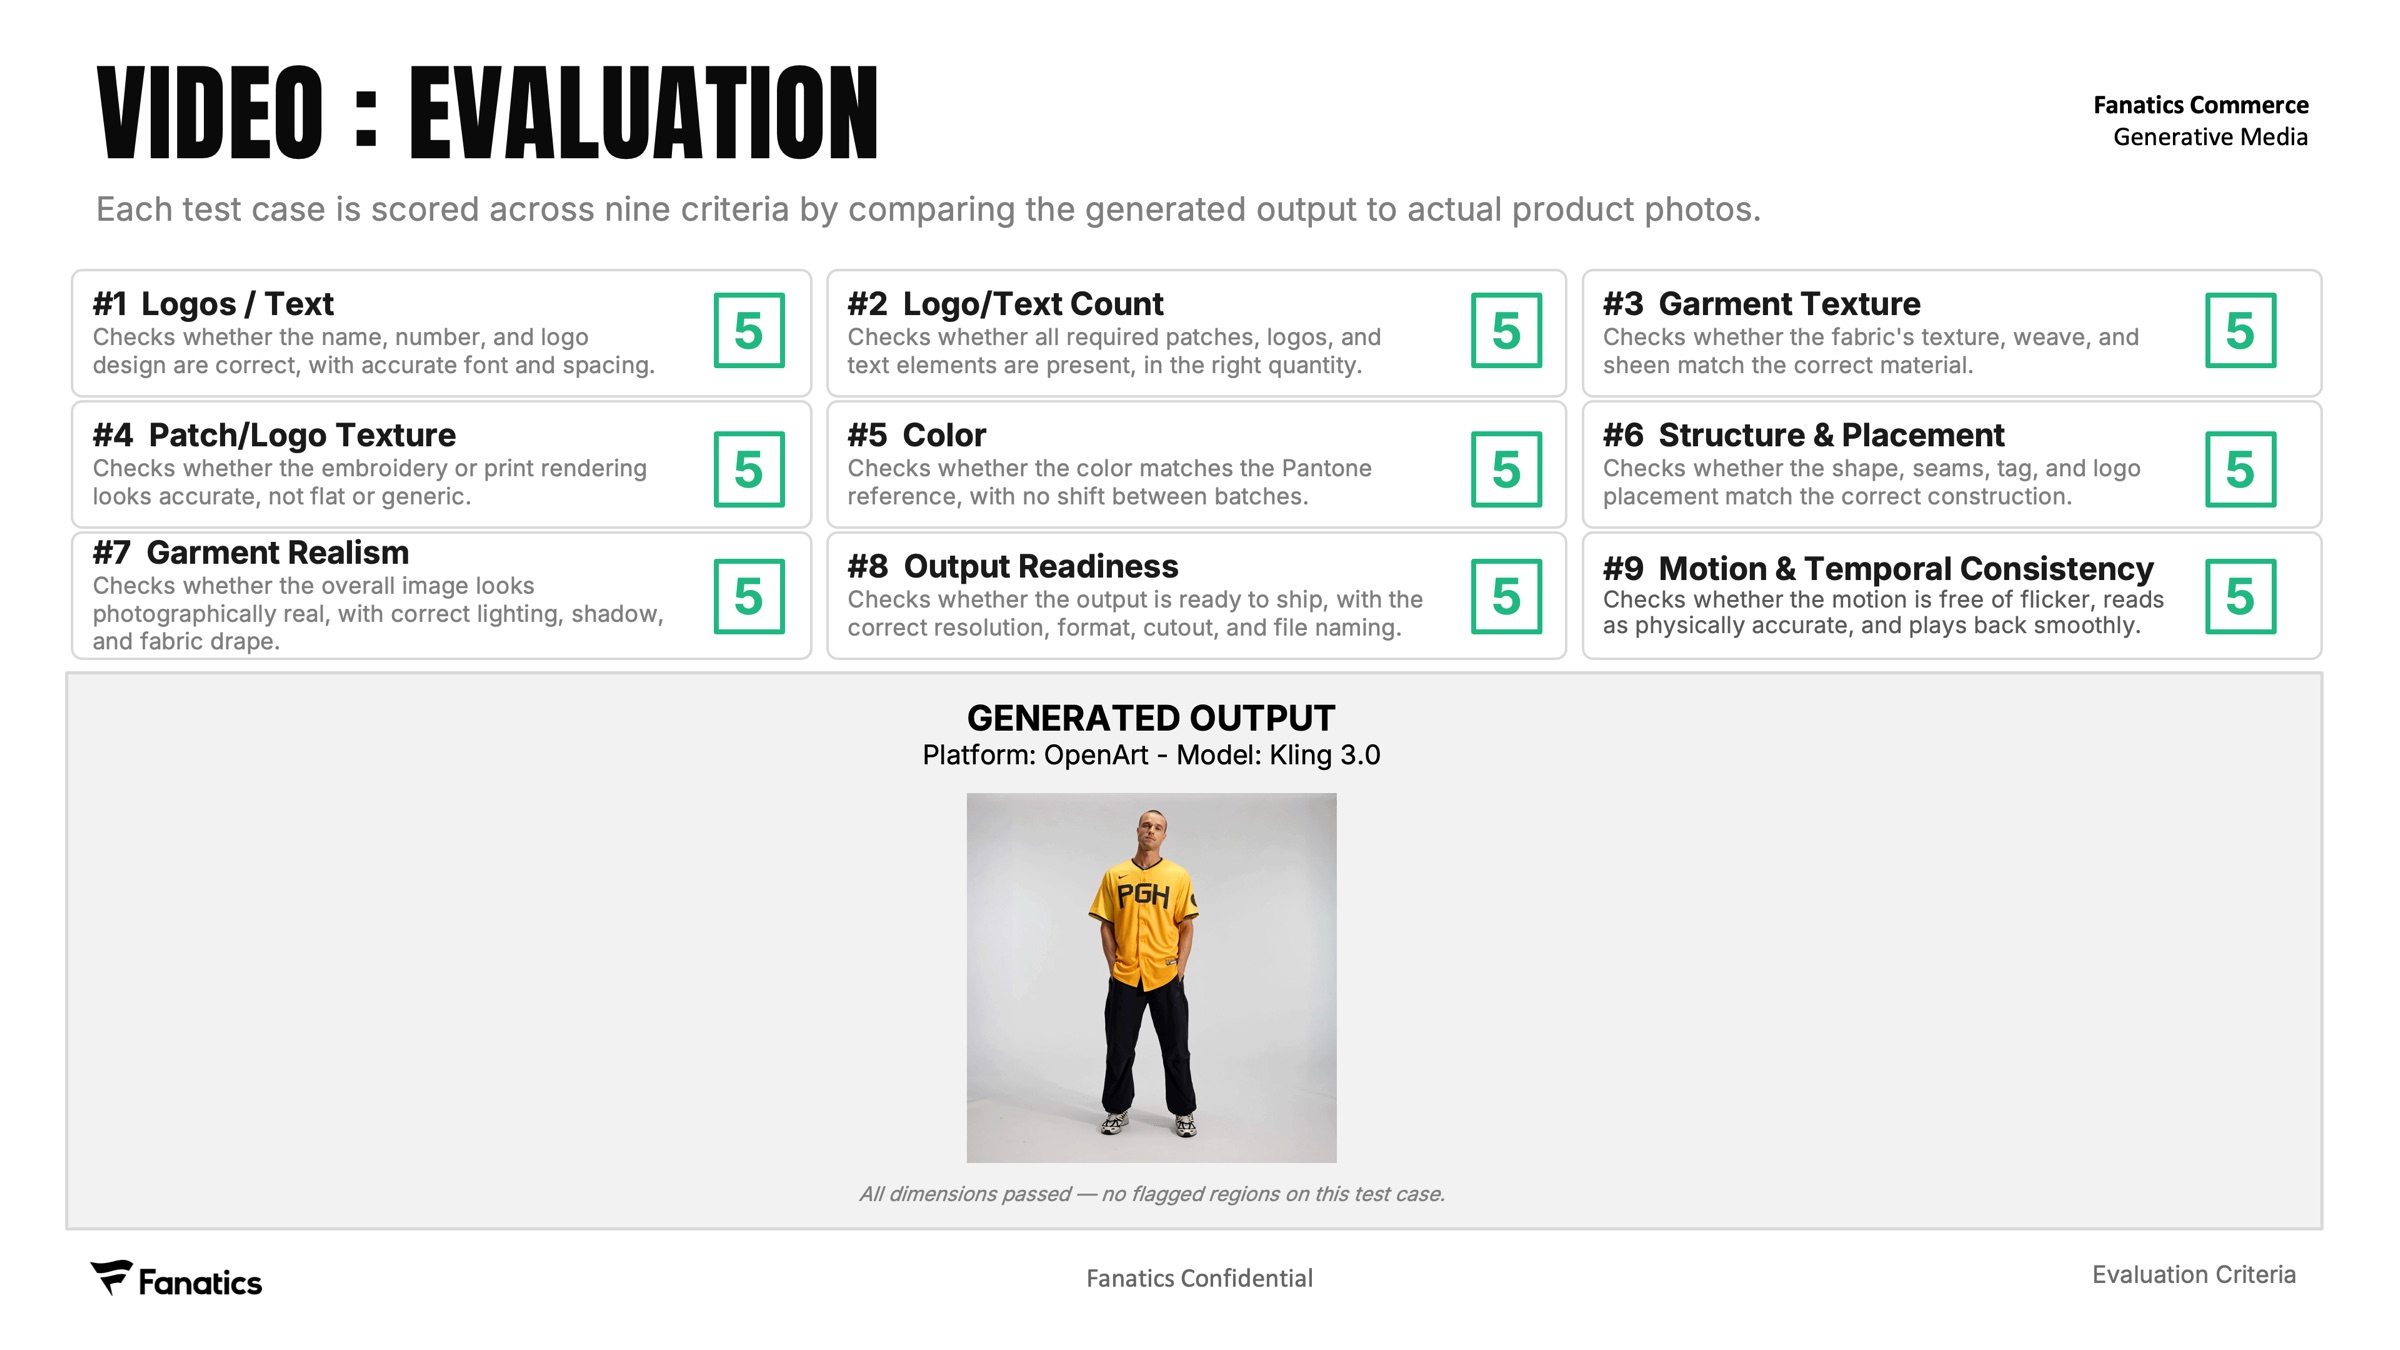
Every output is compared to the art file on eight criteria; video adds a ninth for motion.
Scoring
High-Risk Zones
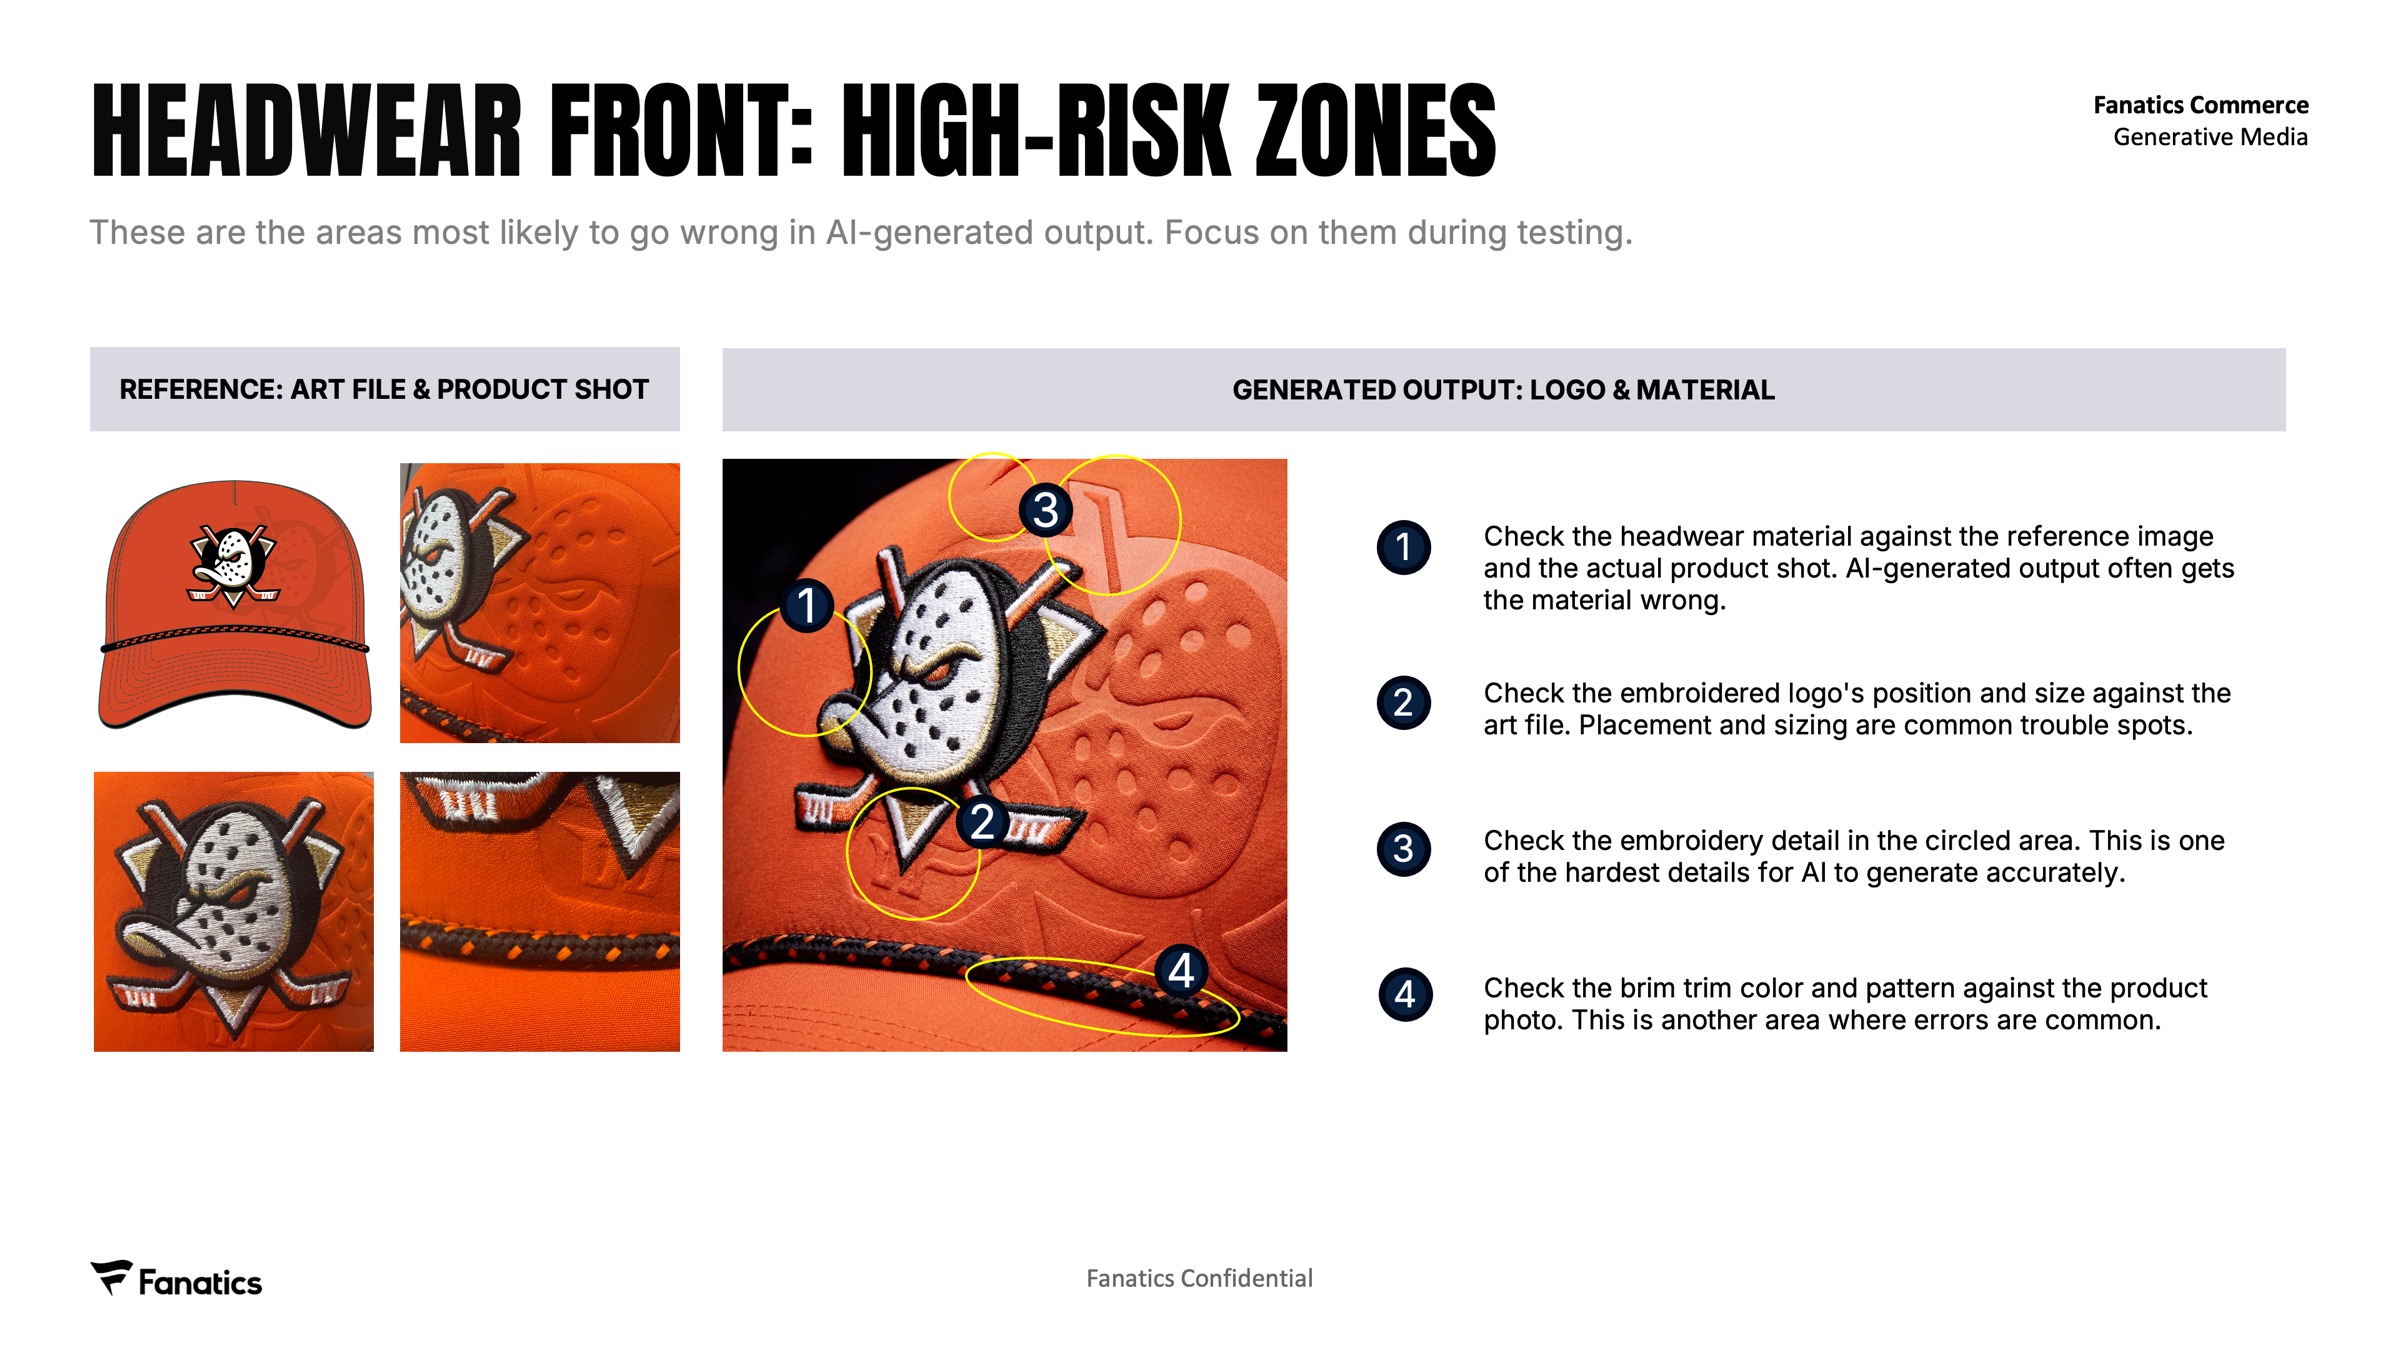
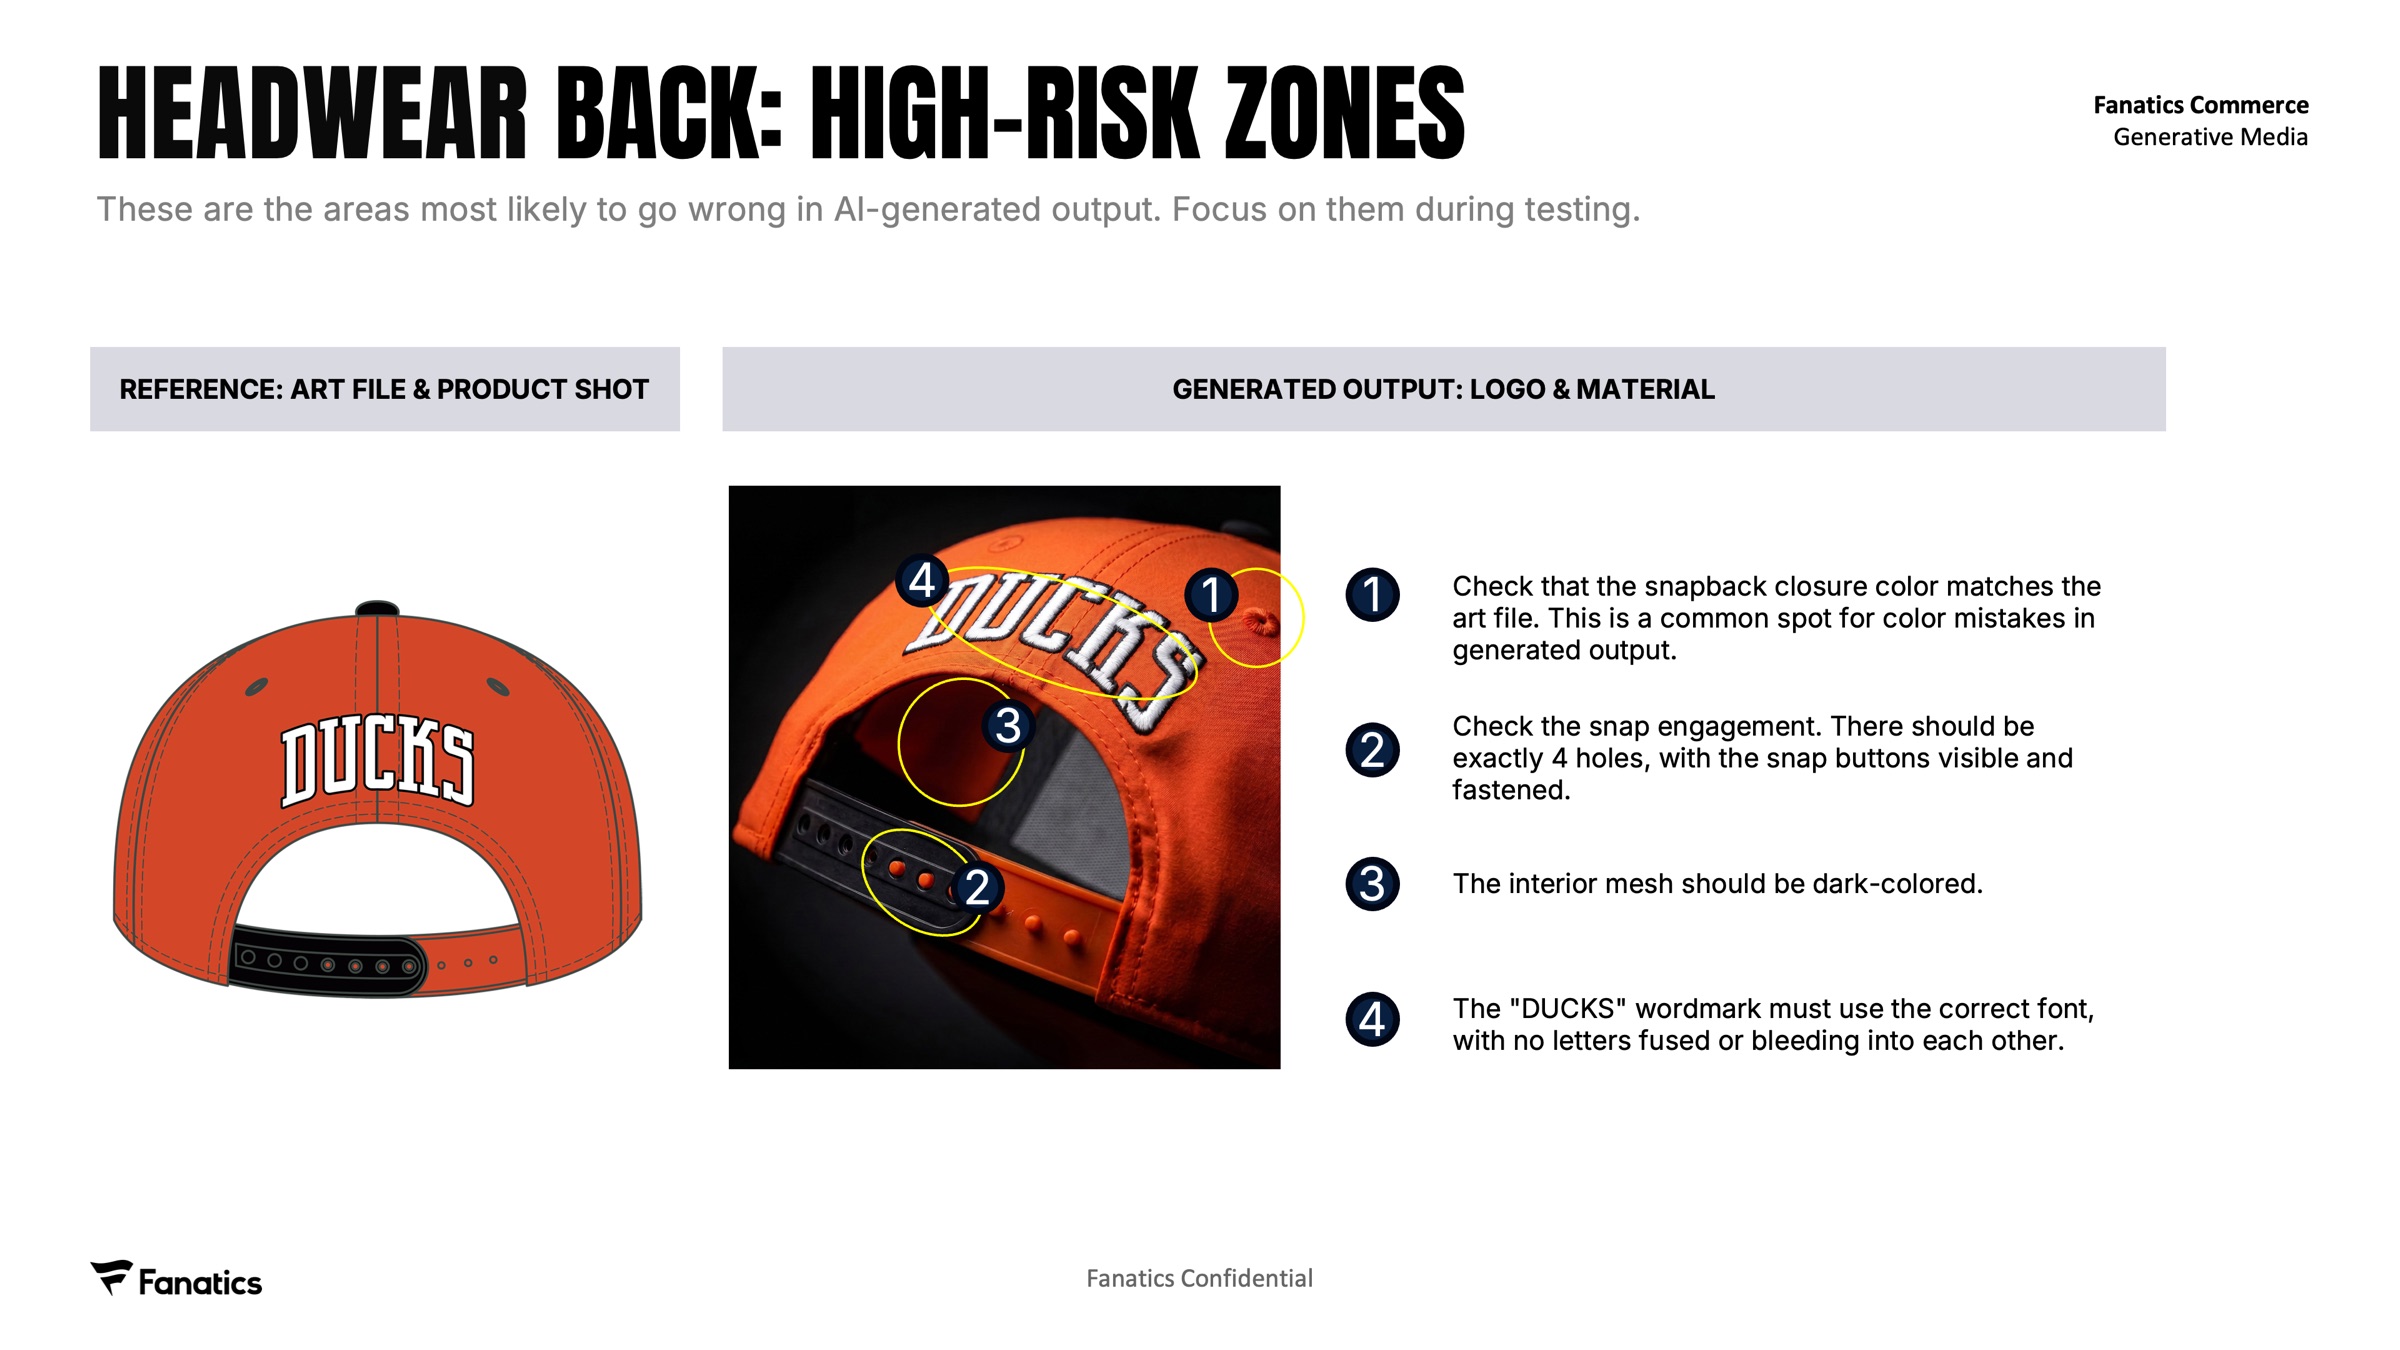
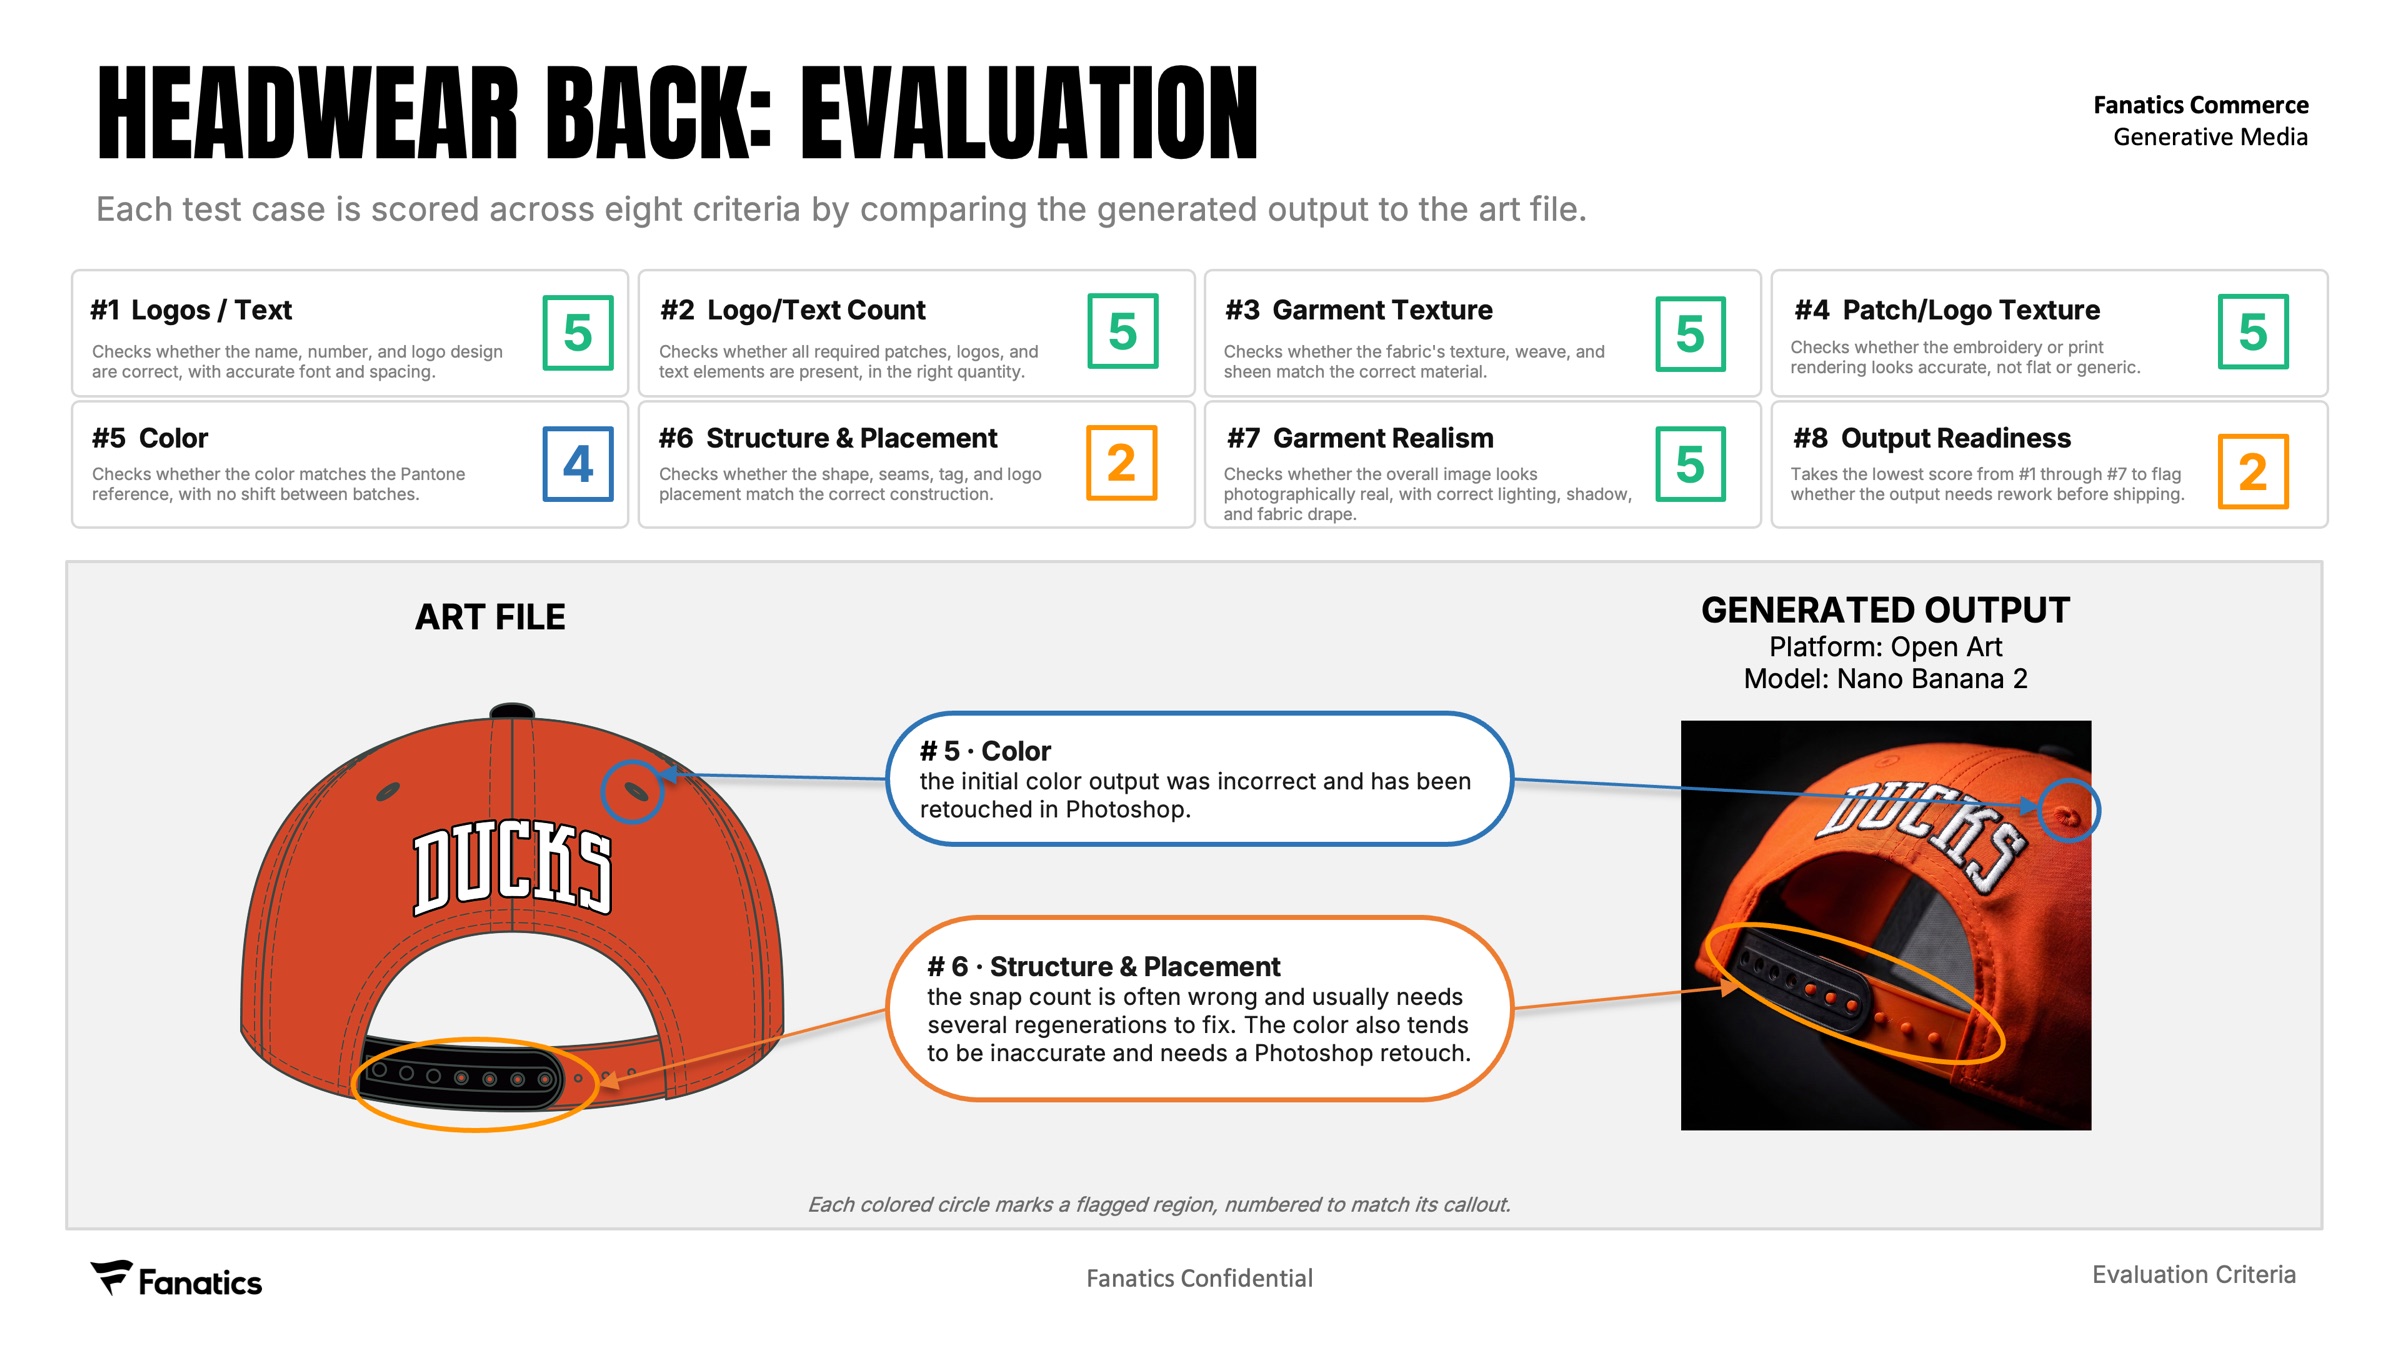
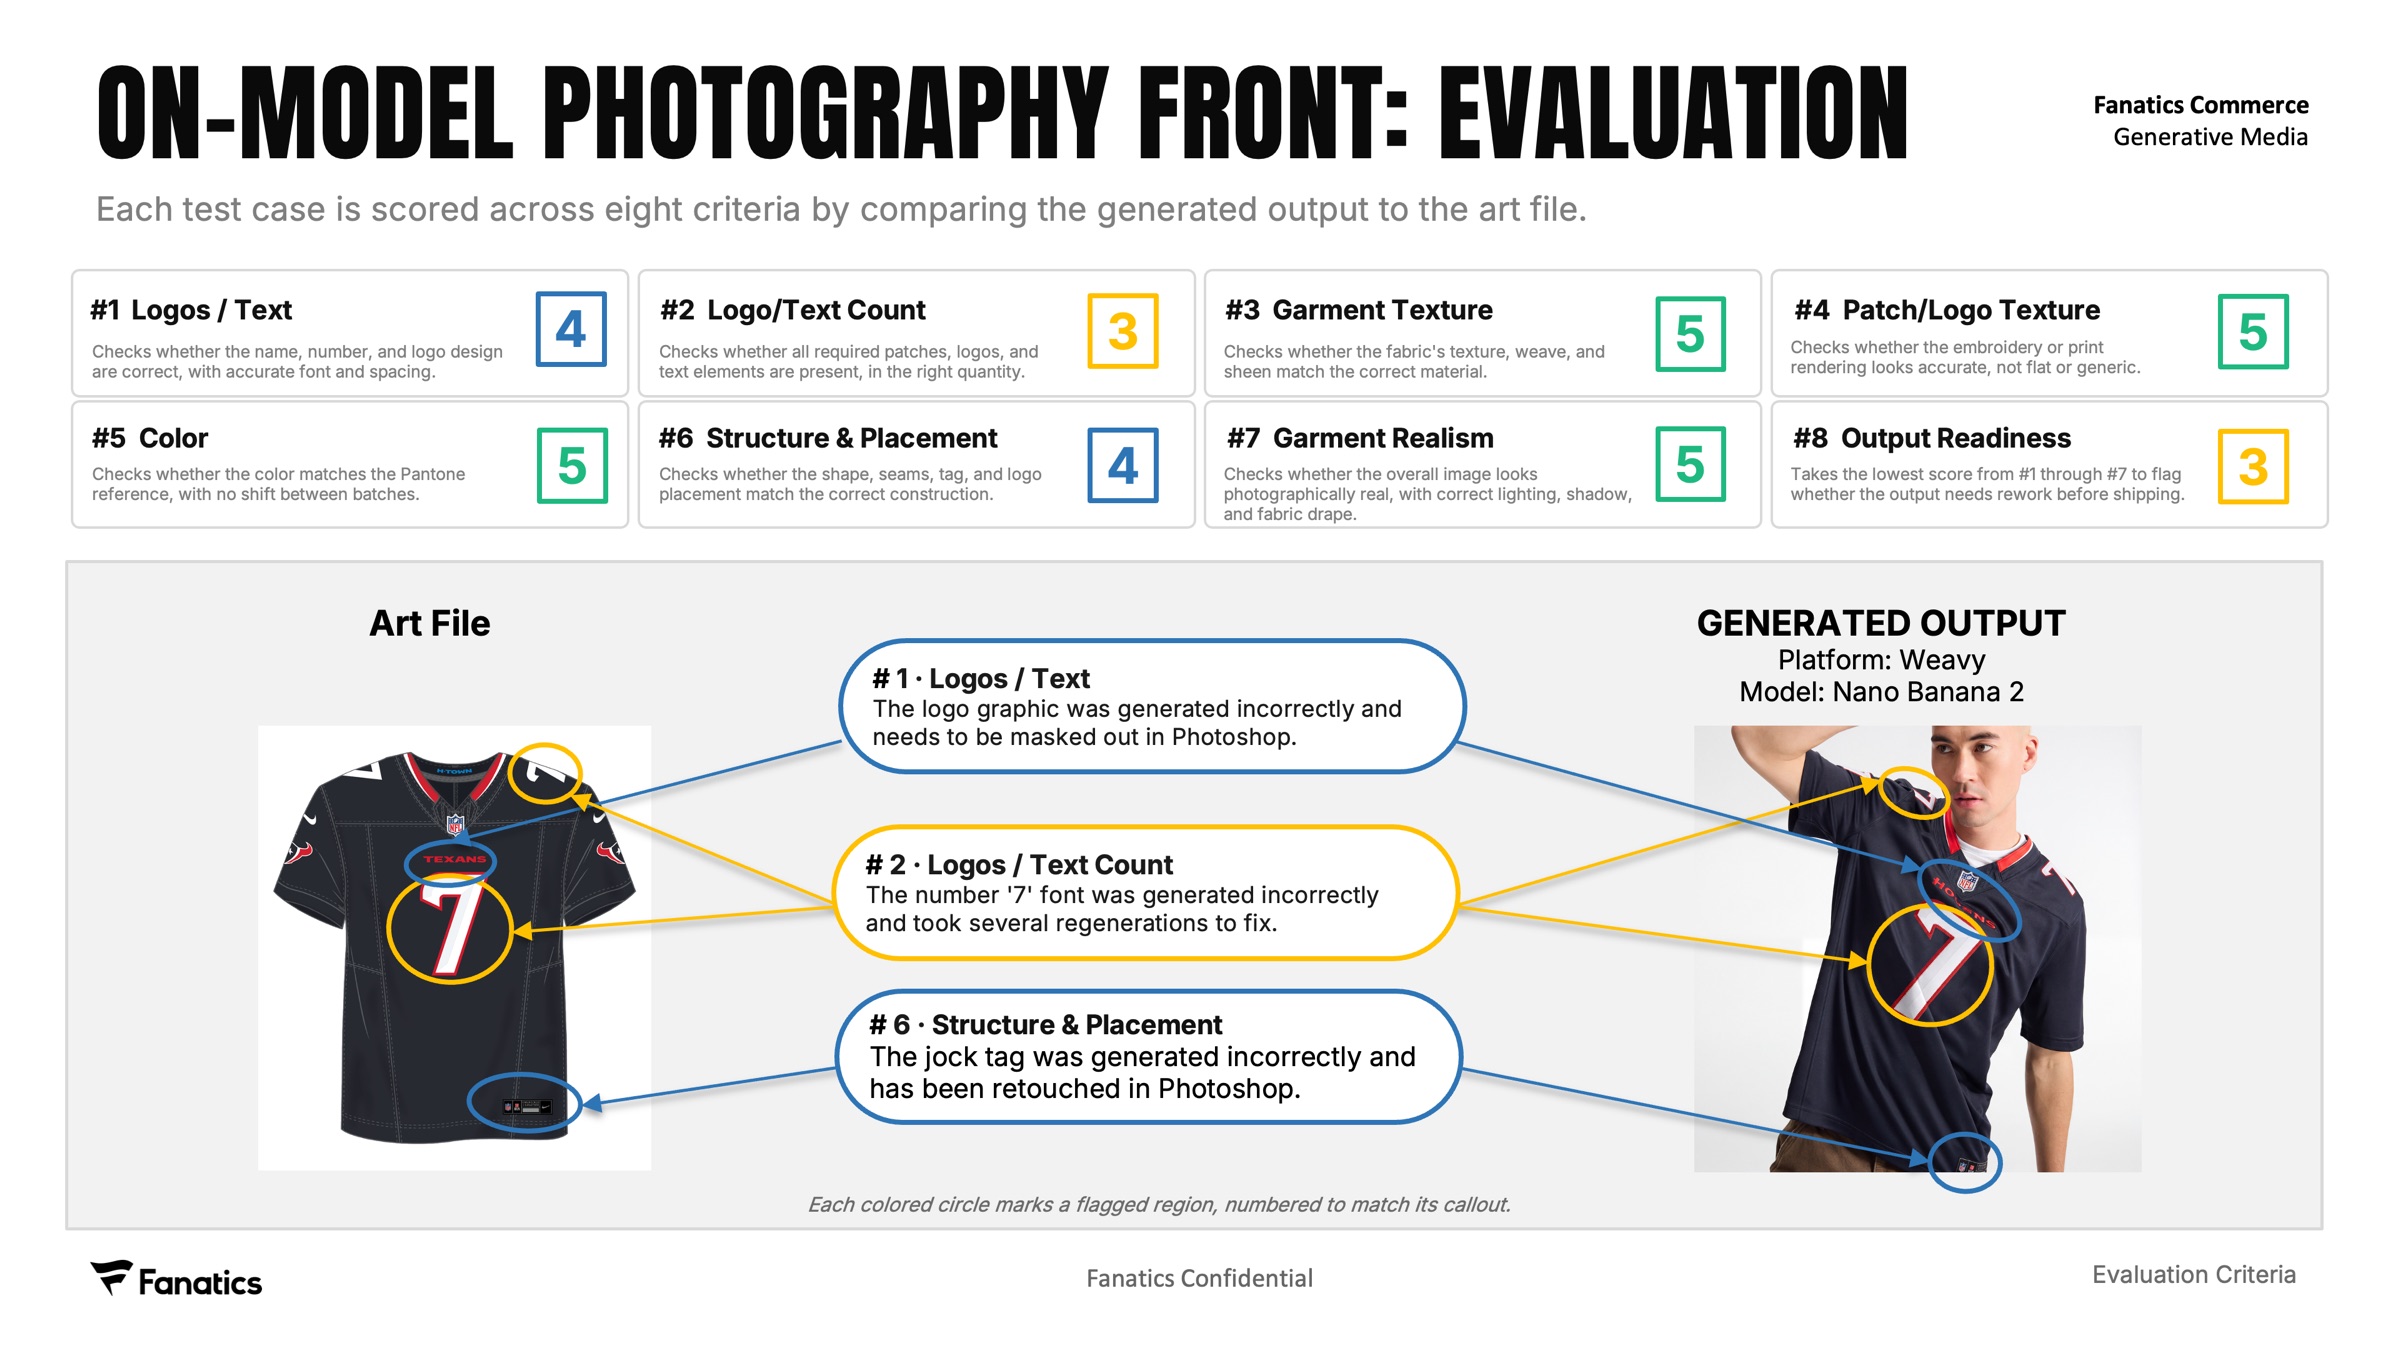
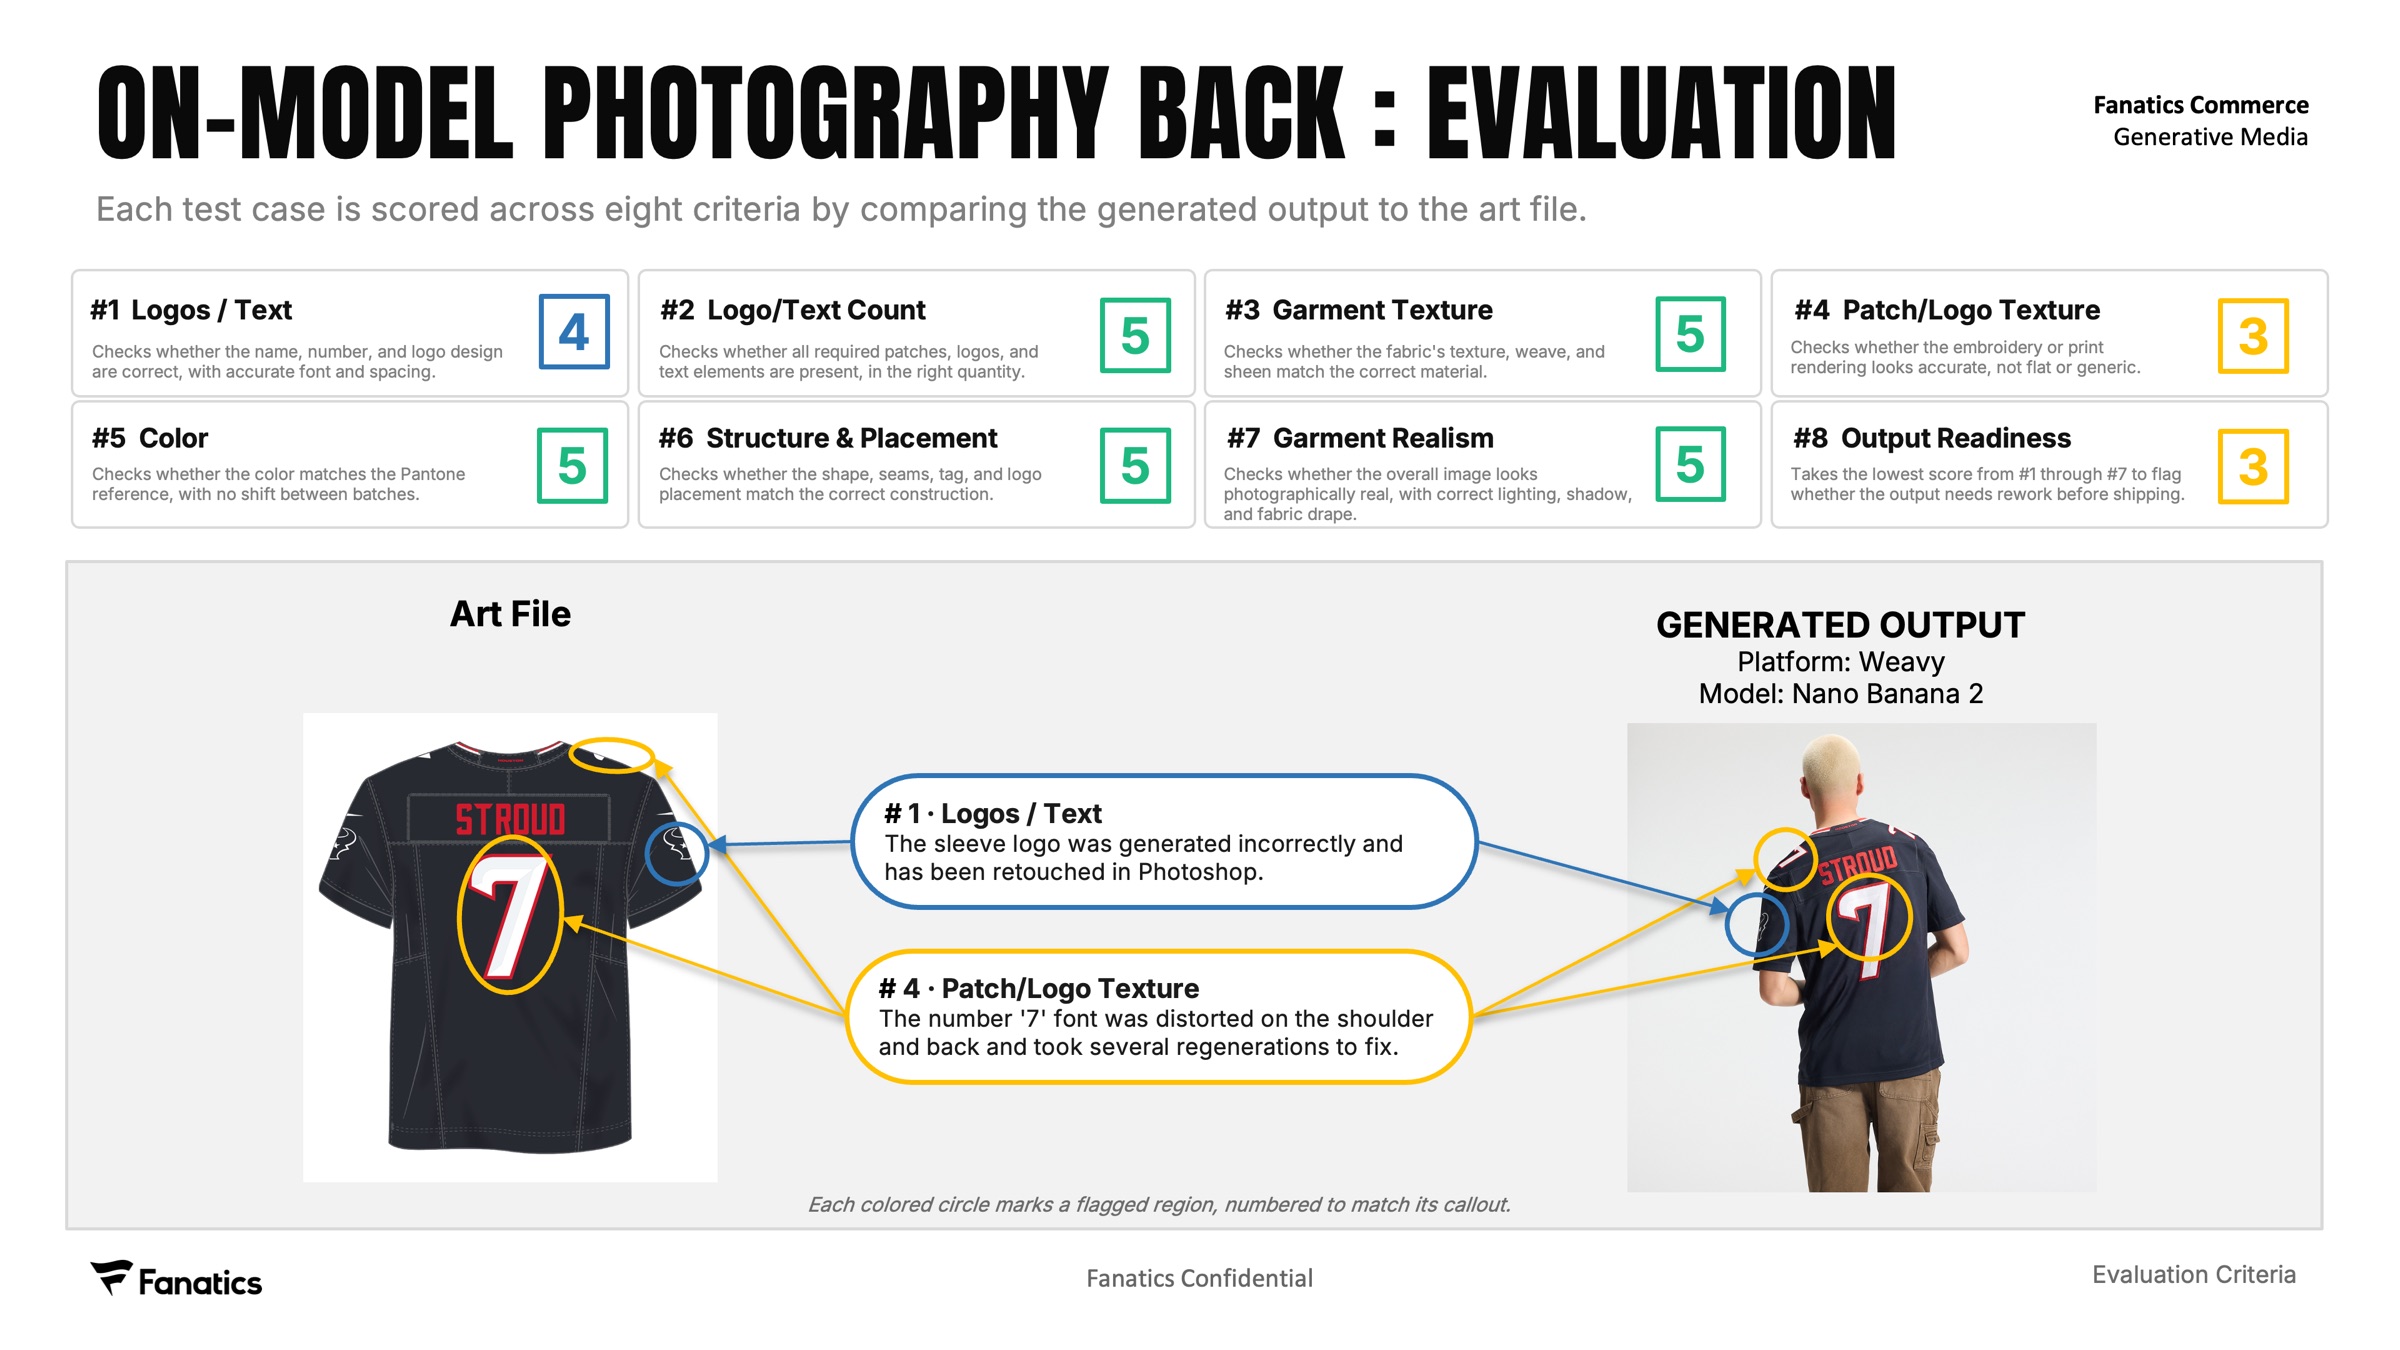
For each case I mapped where AI output most often goes wrong, so review time goes to the places that matter: logo placement and embroidery, snap counts, numeral fonts, invented sleeve logos, letter spacing, seams and jock tags.
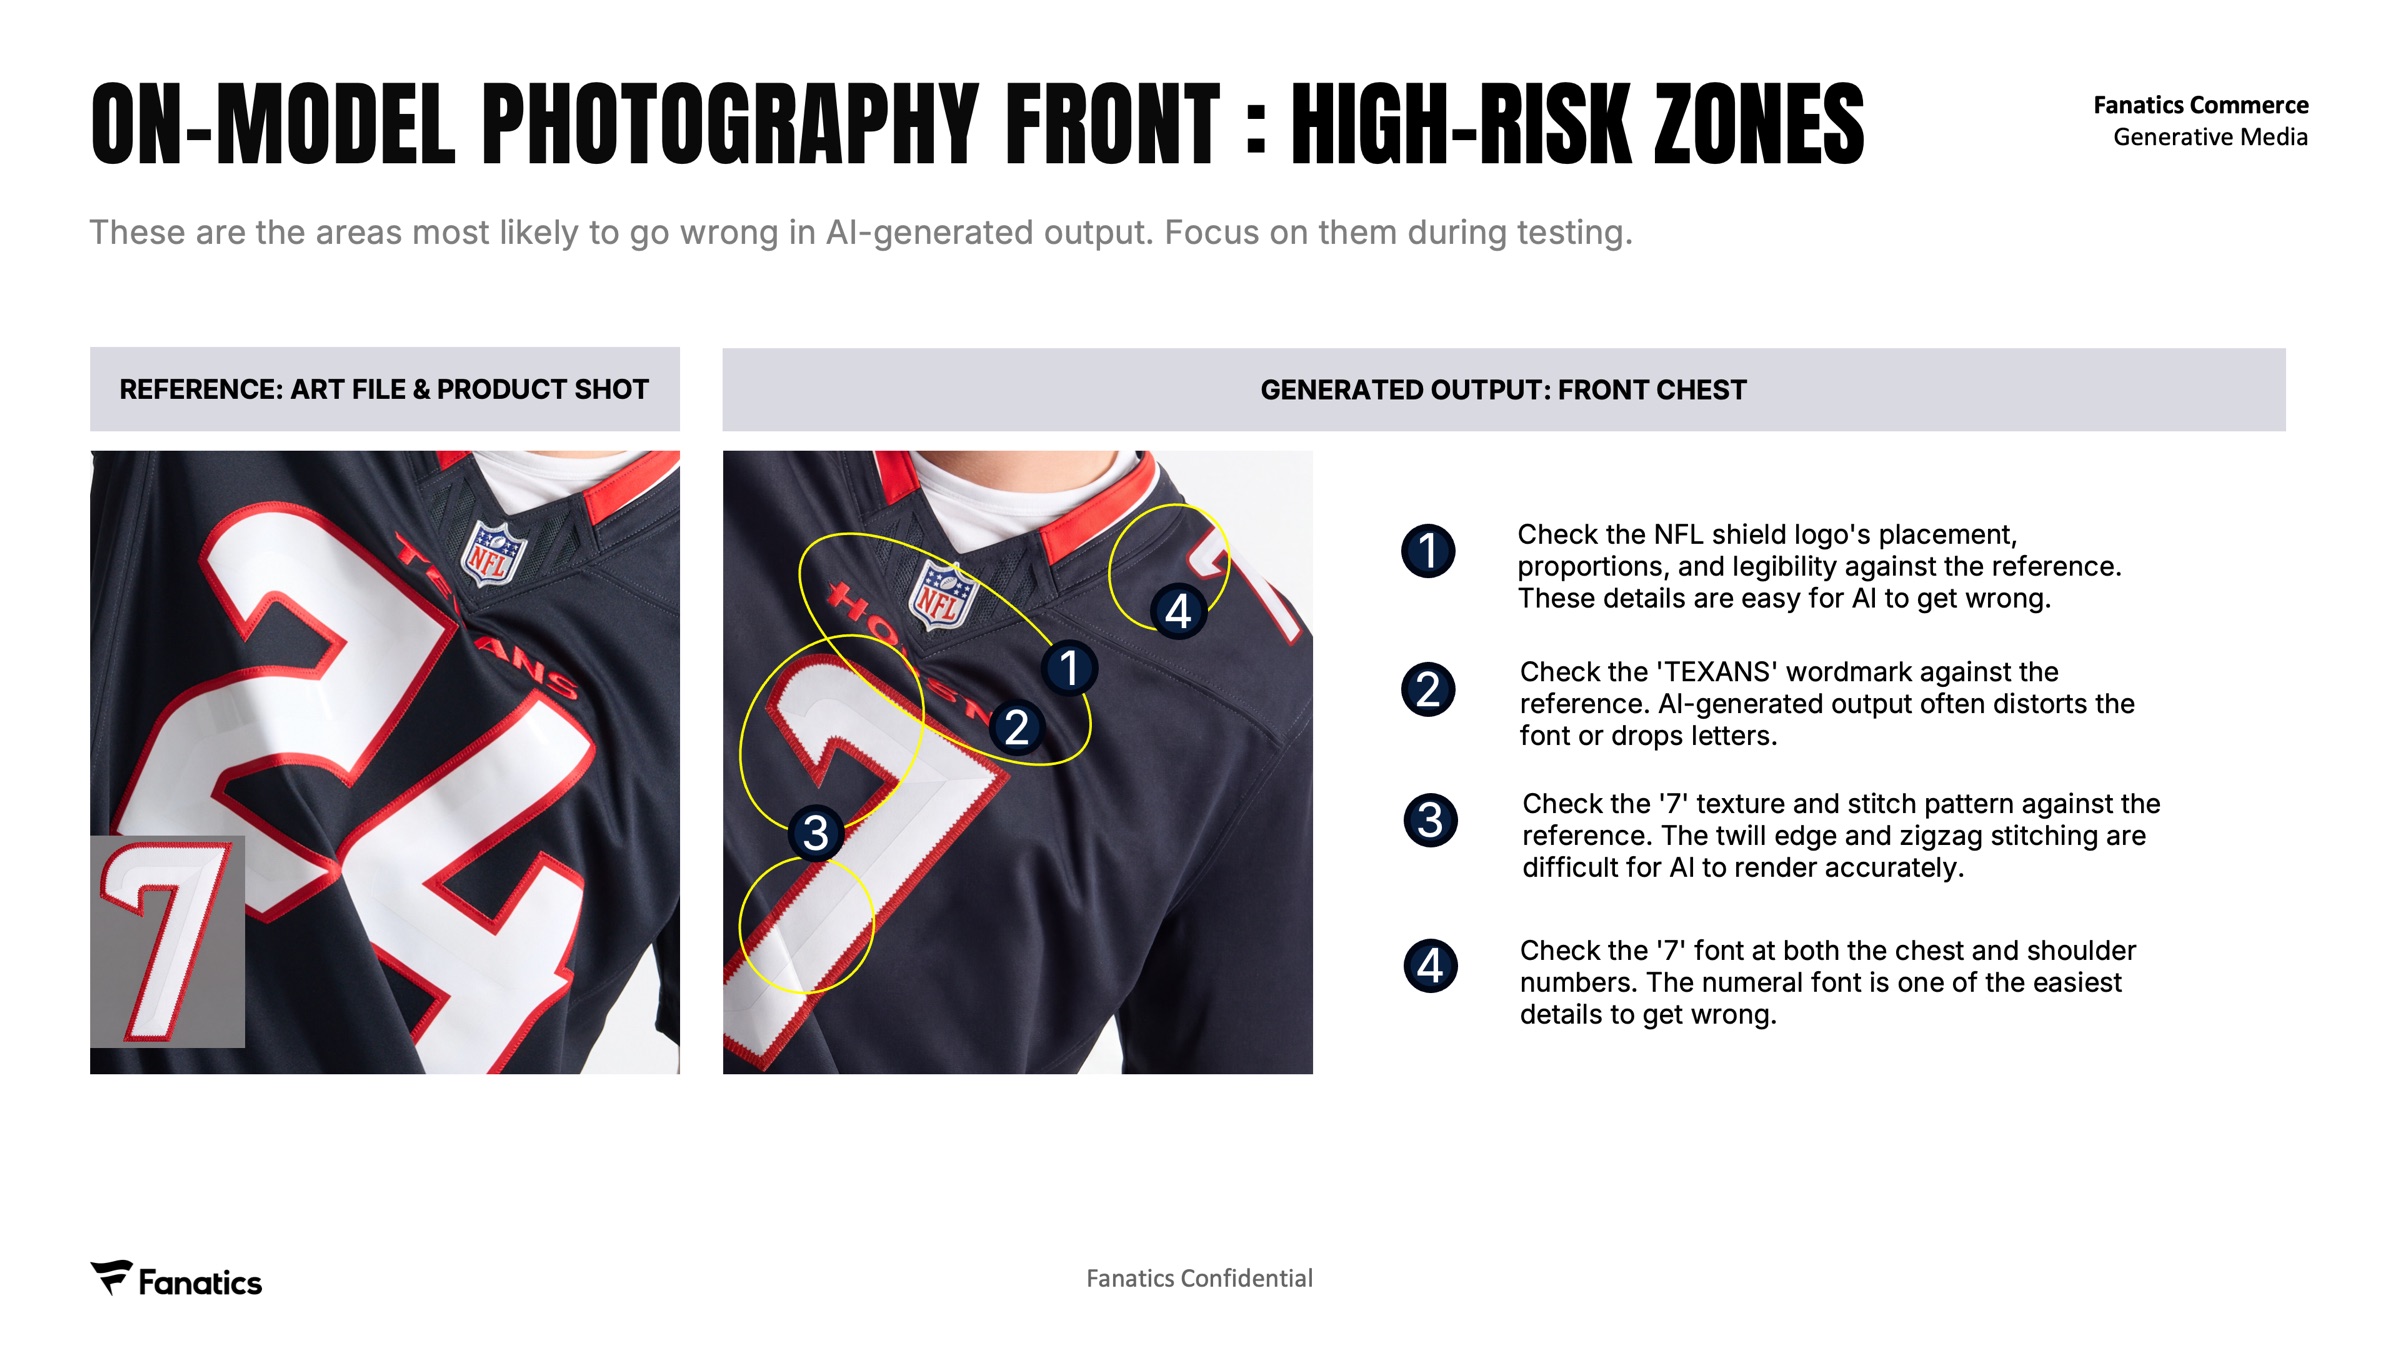
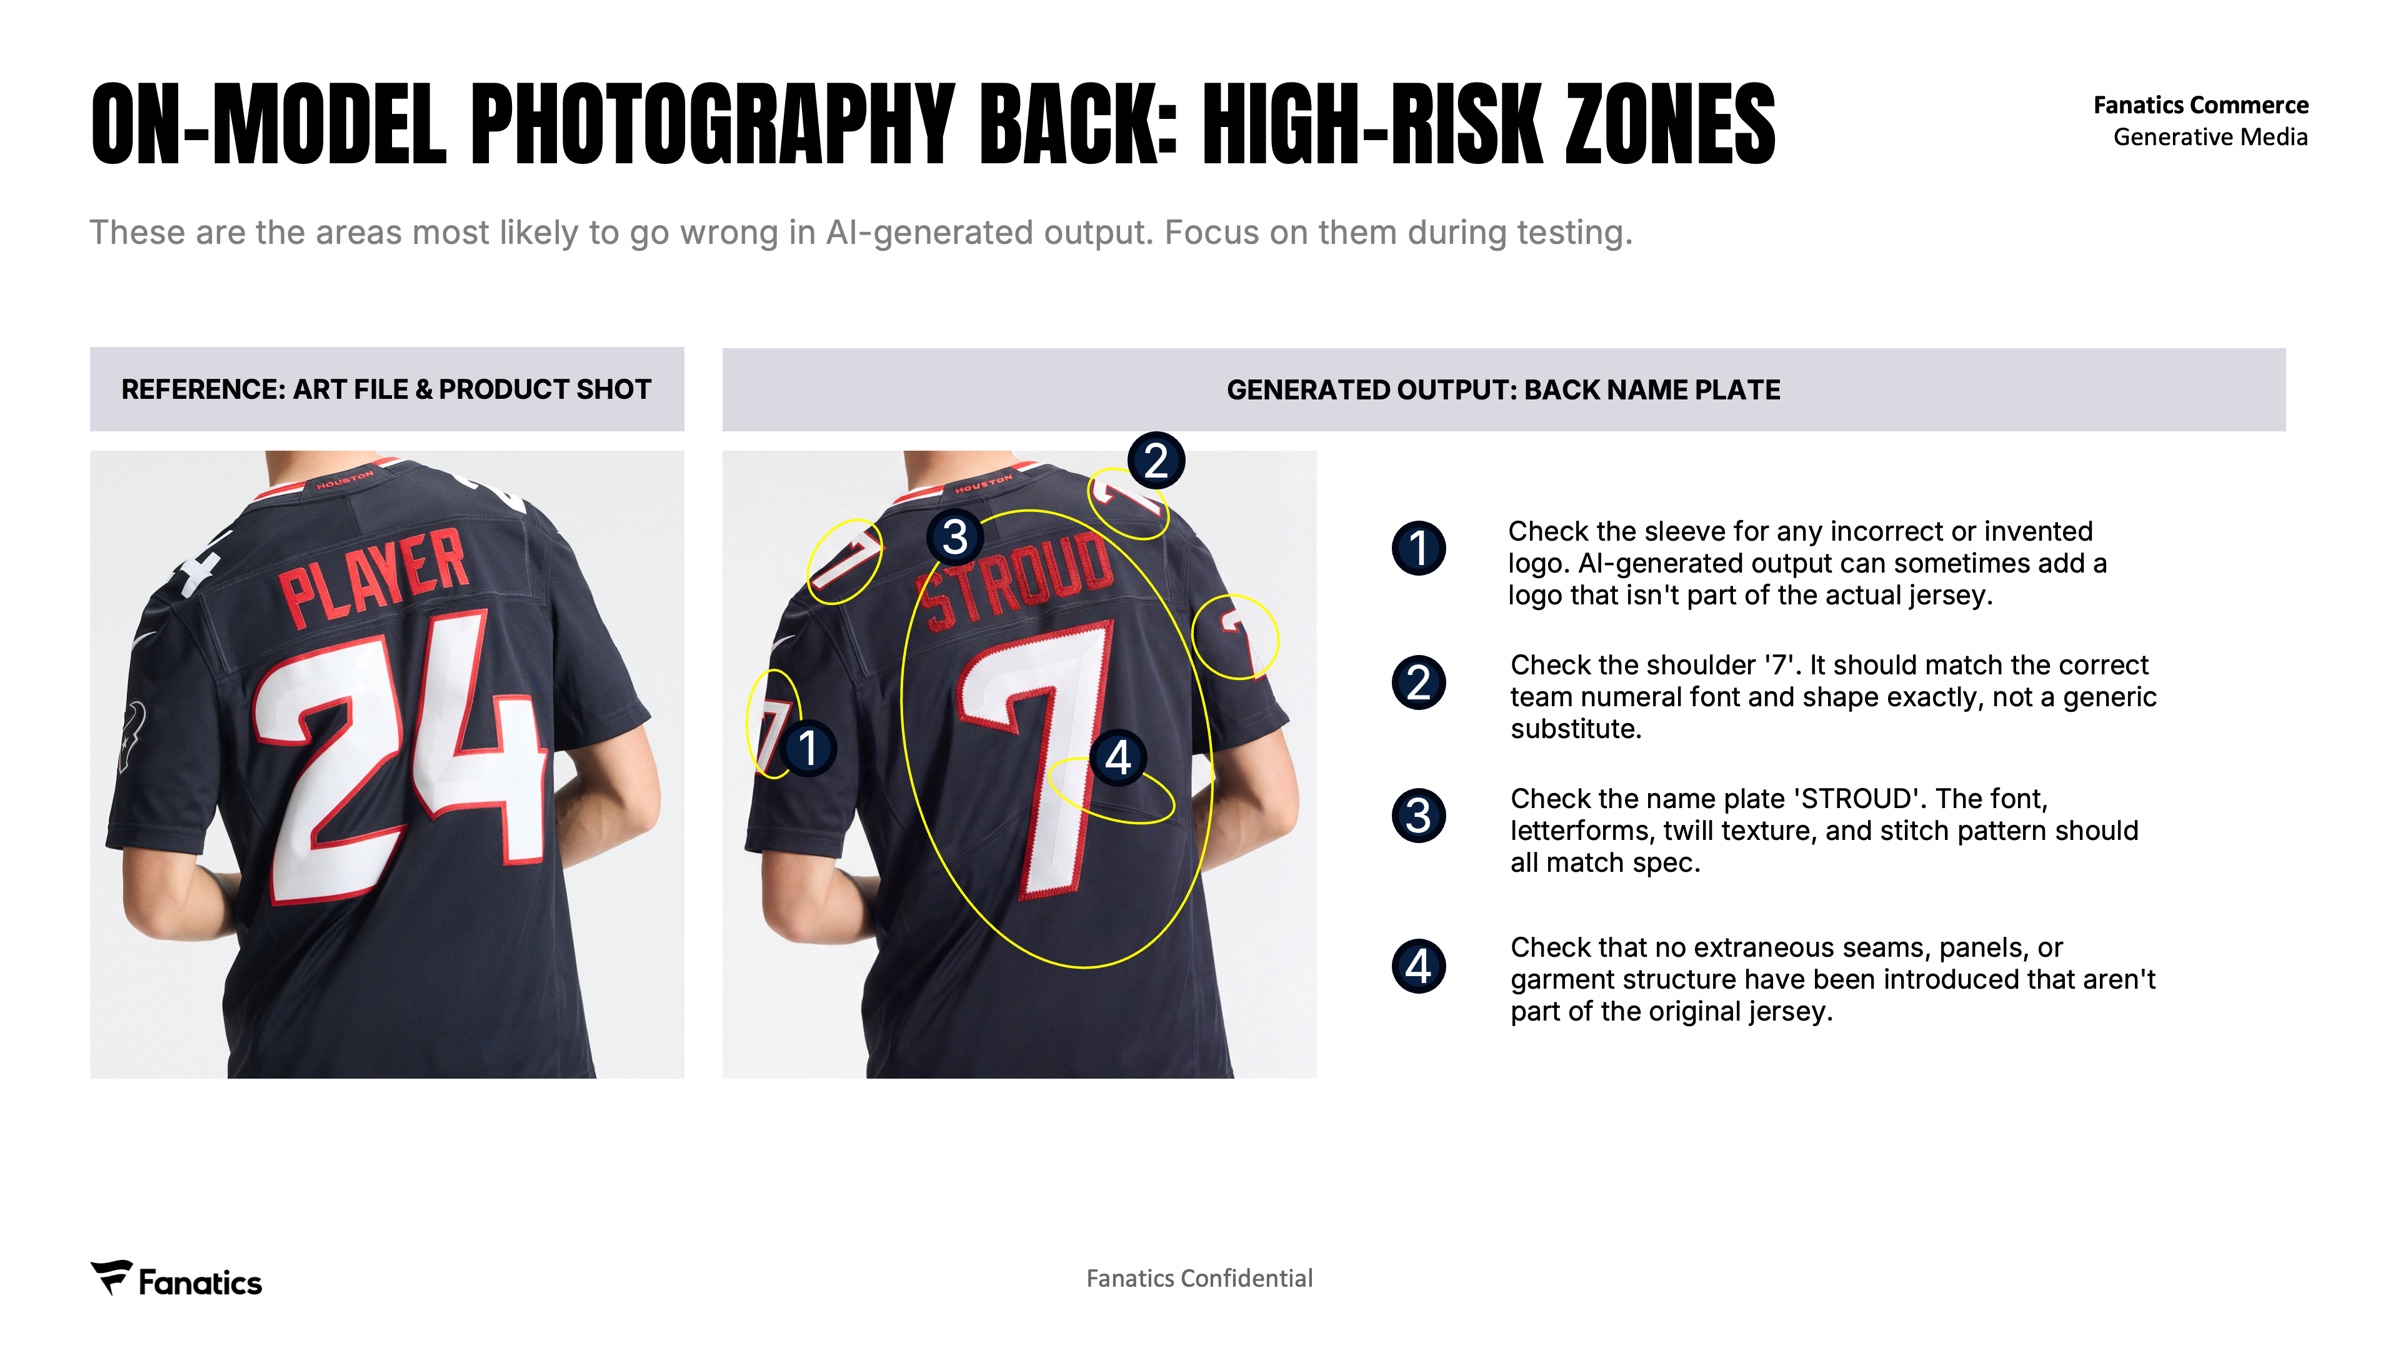
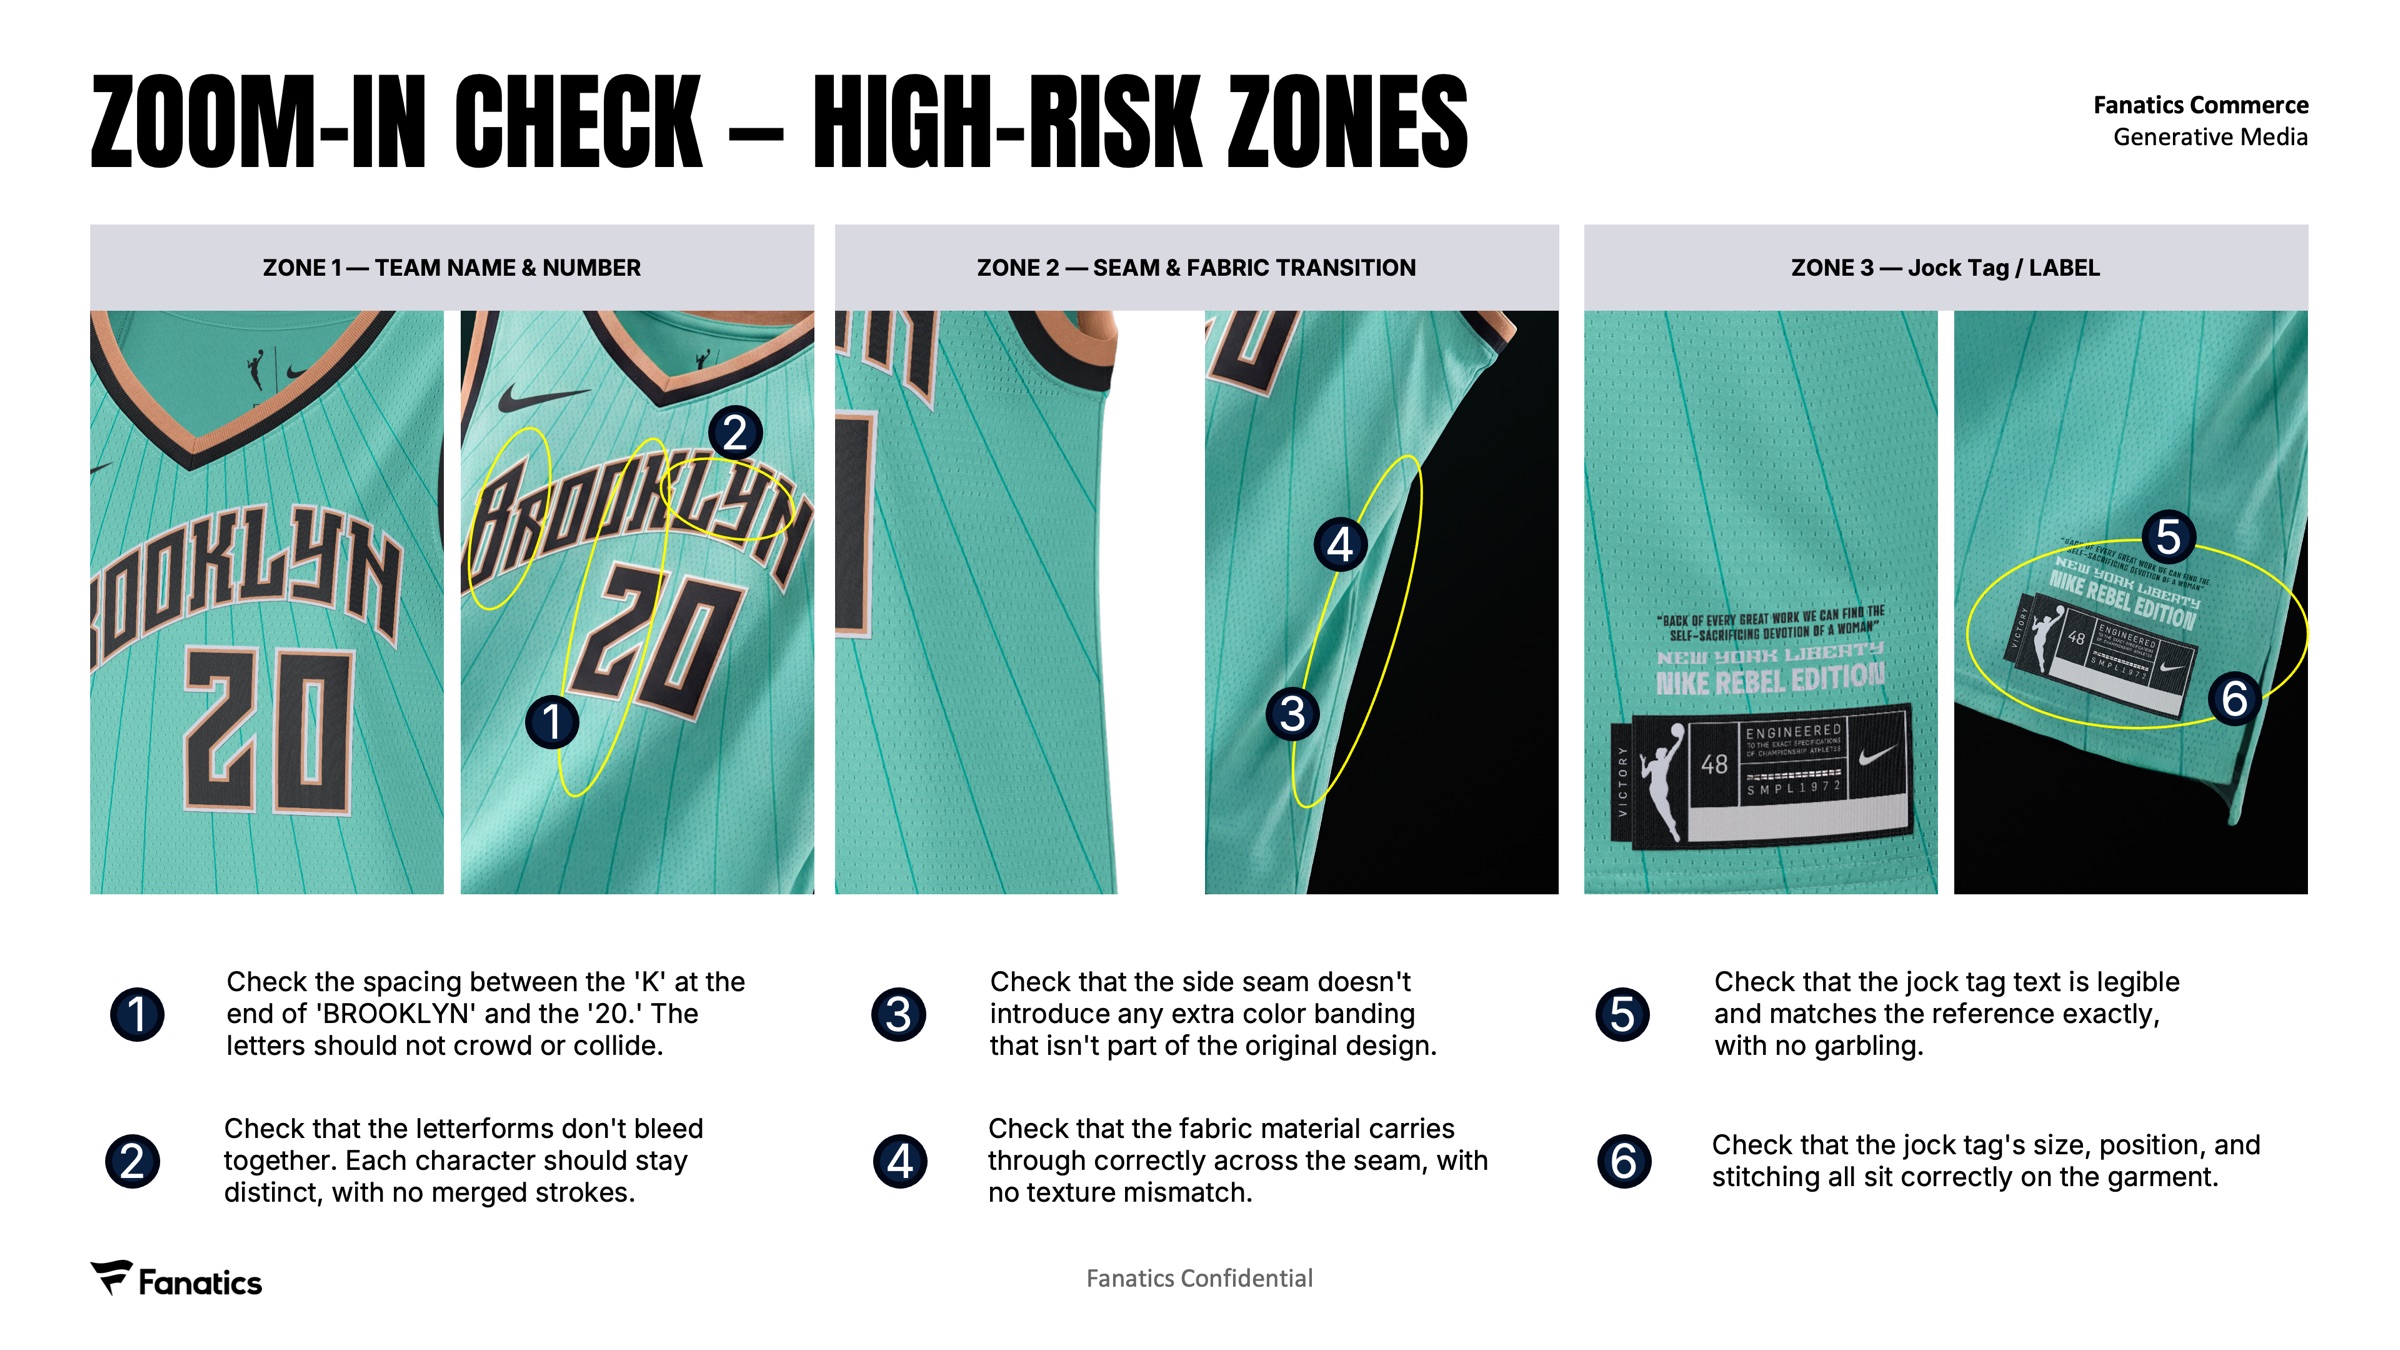
Scored Results
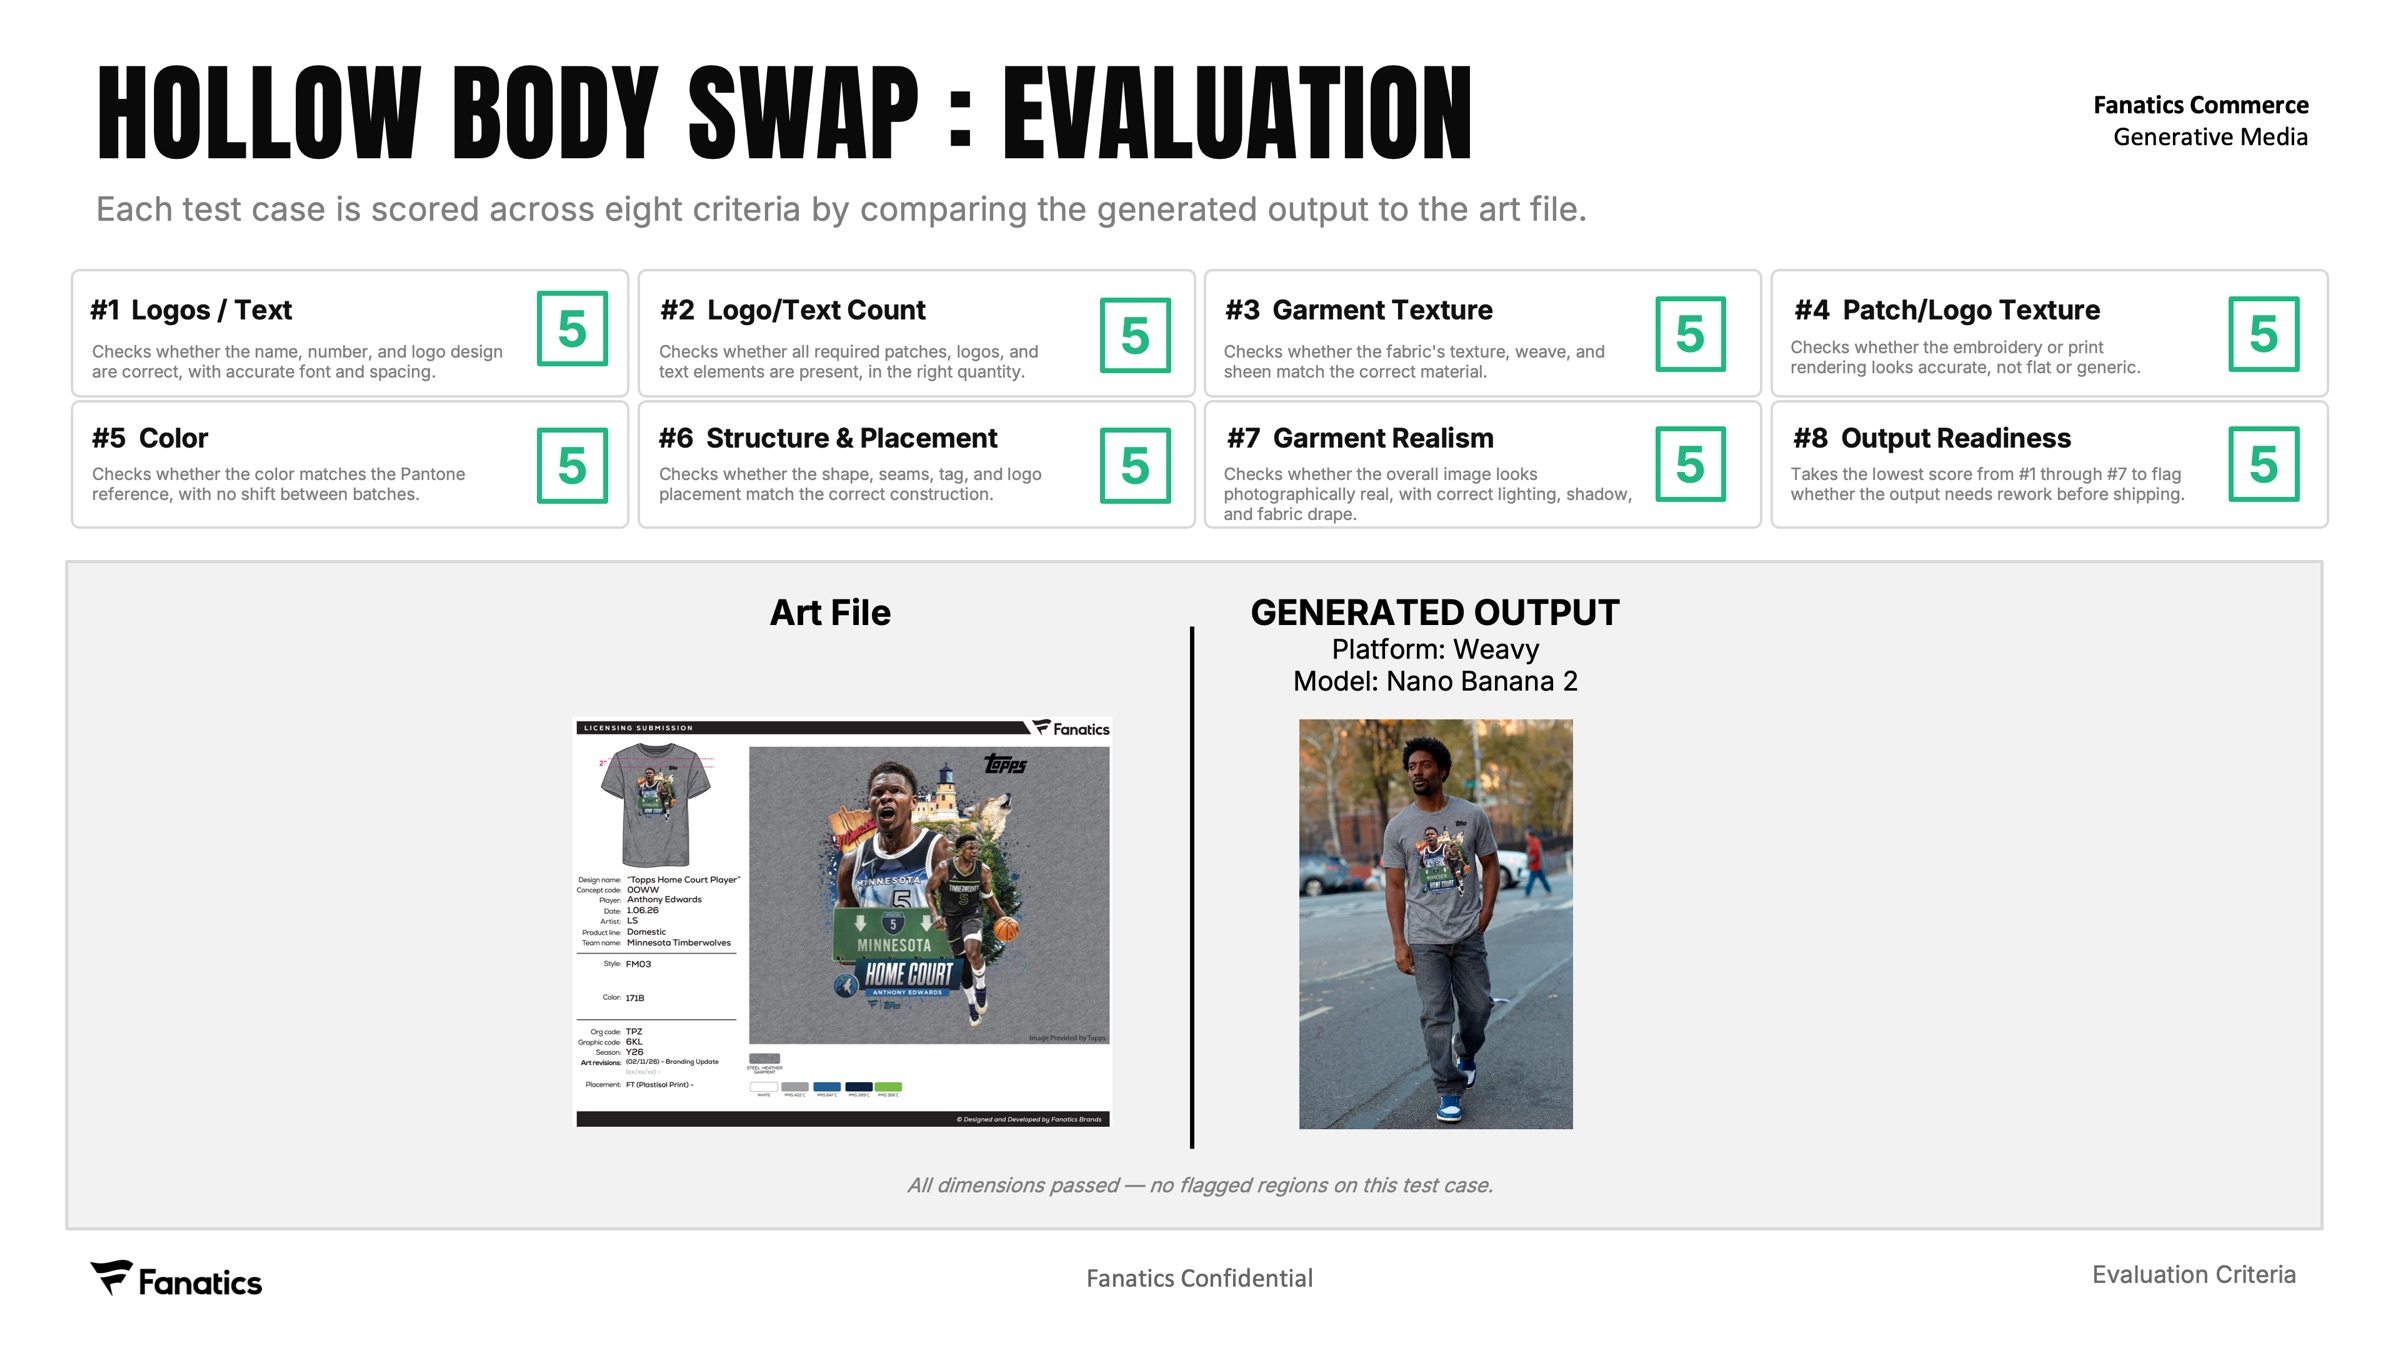
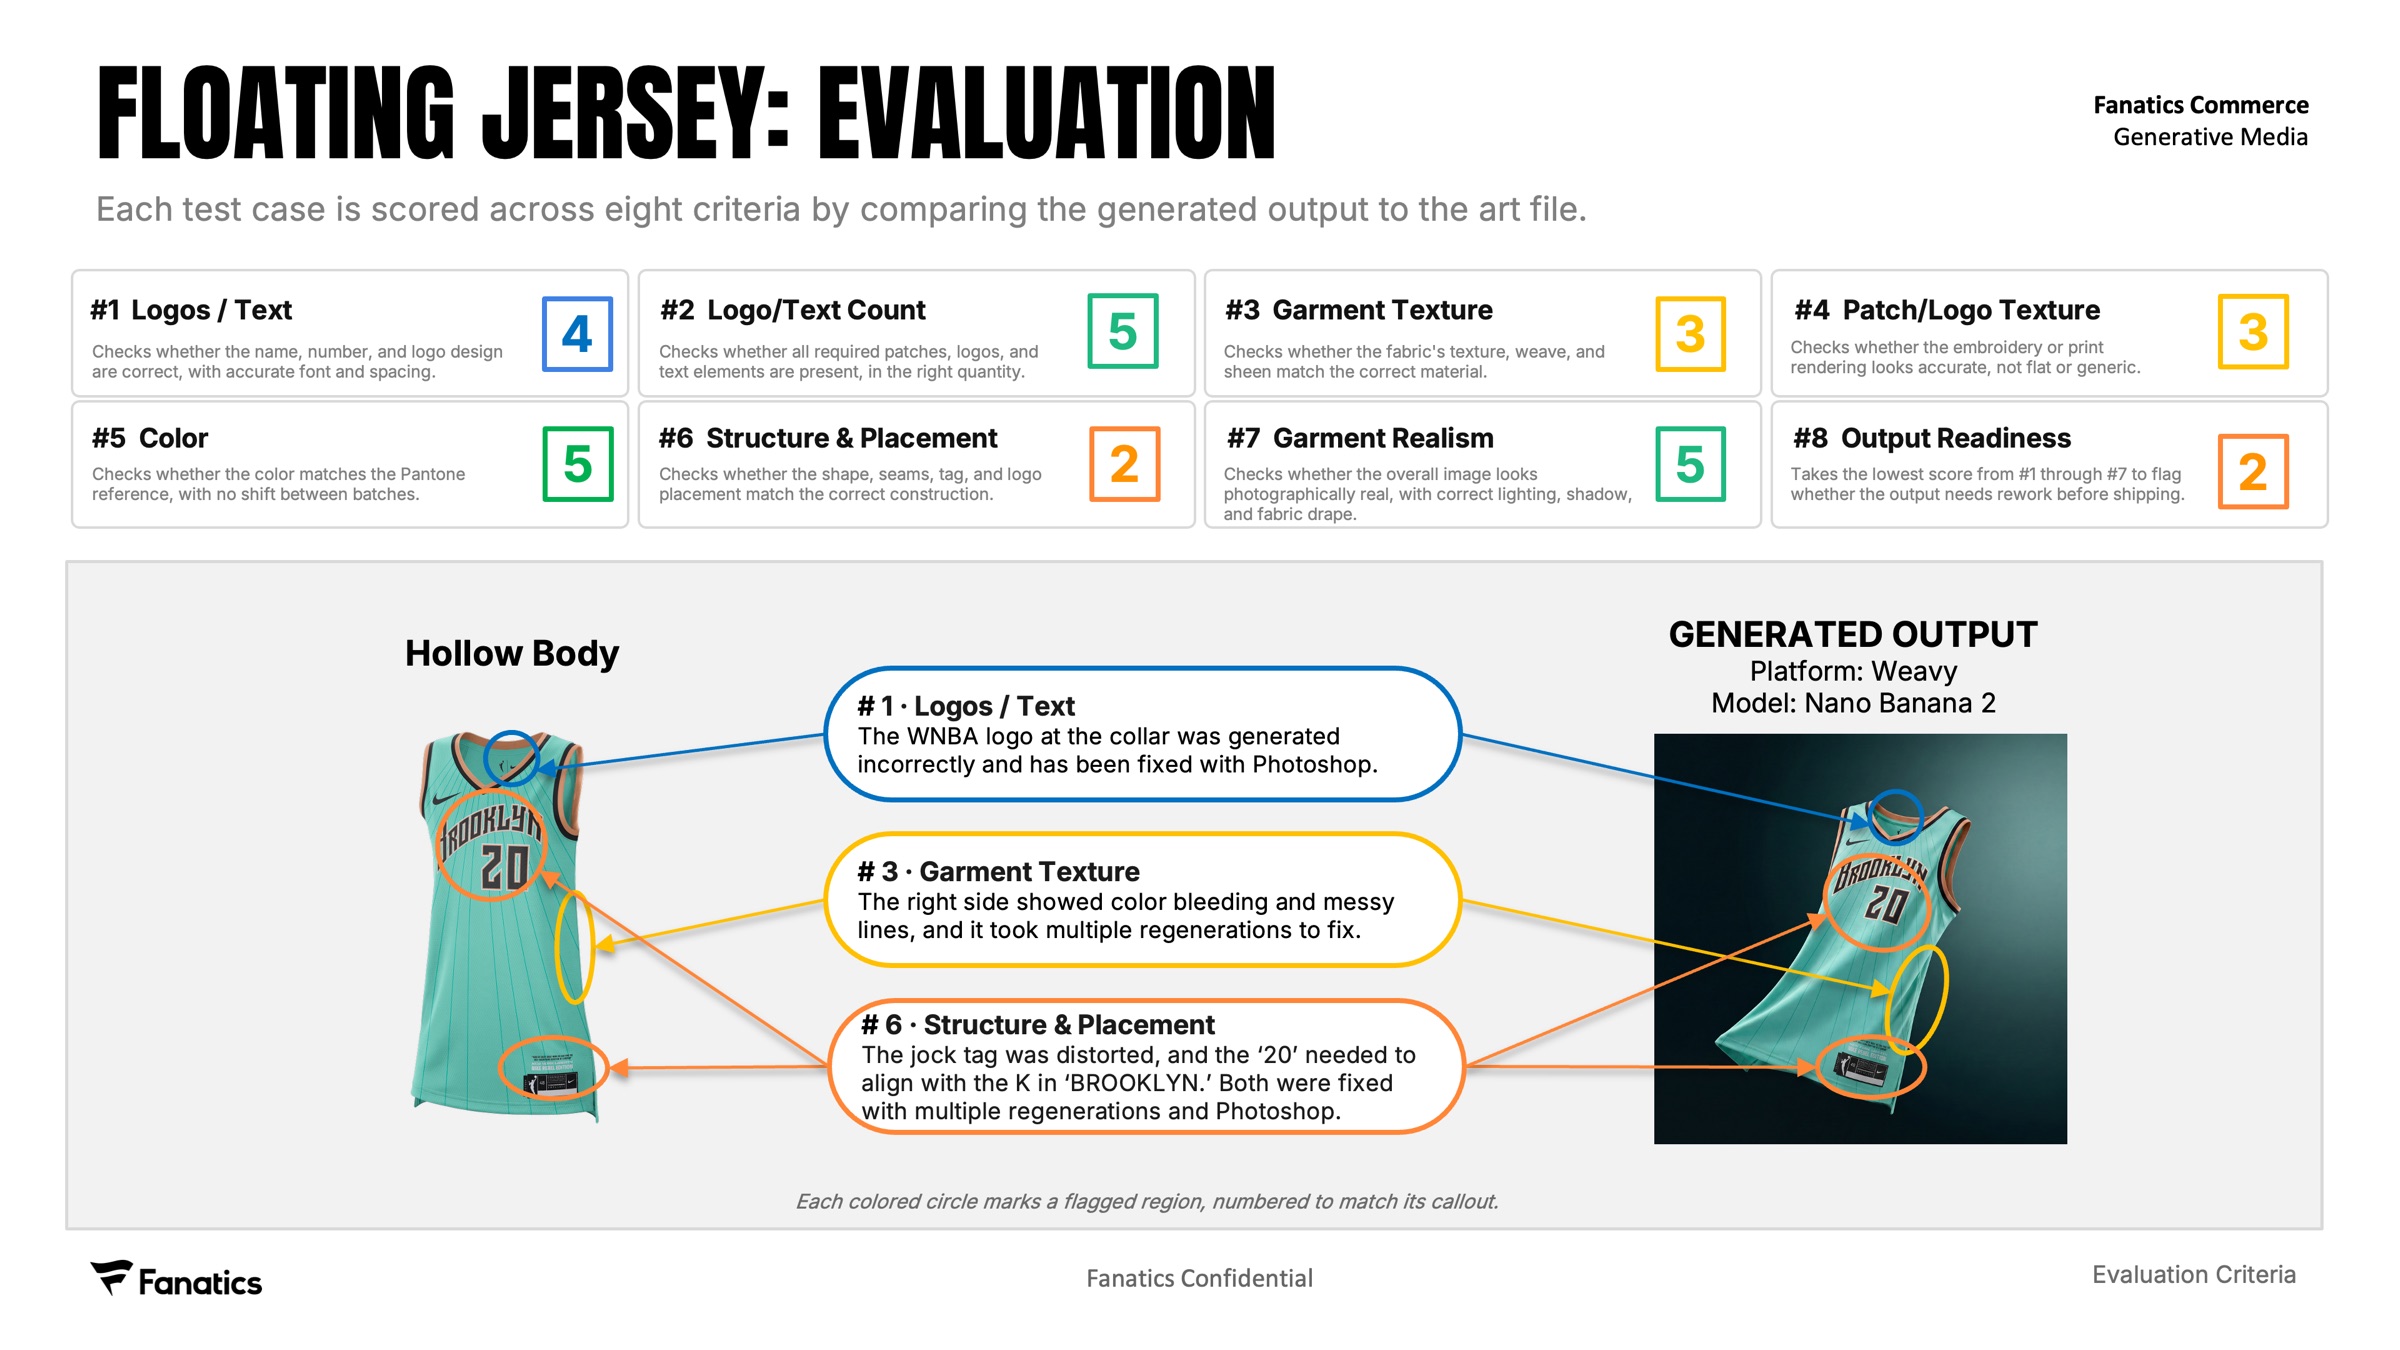
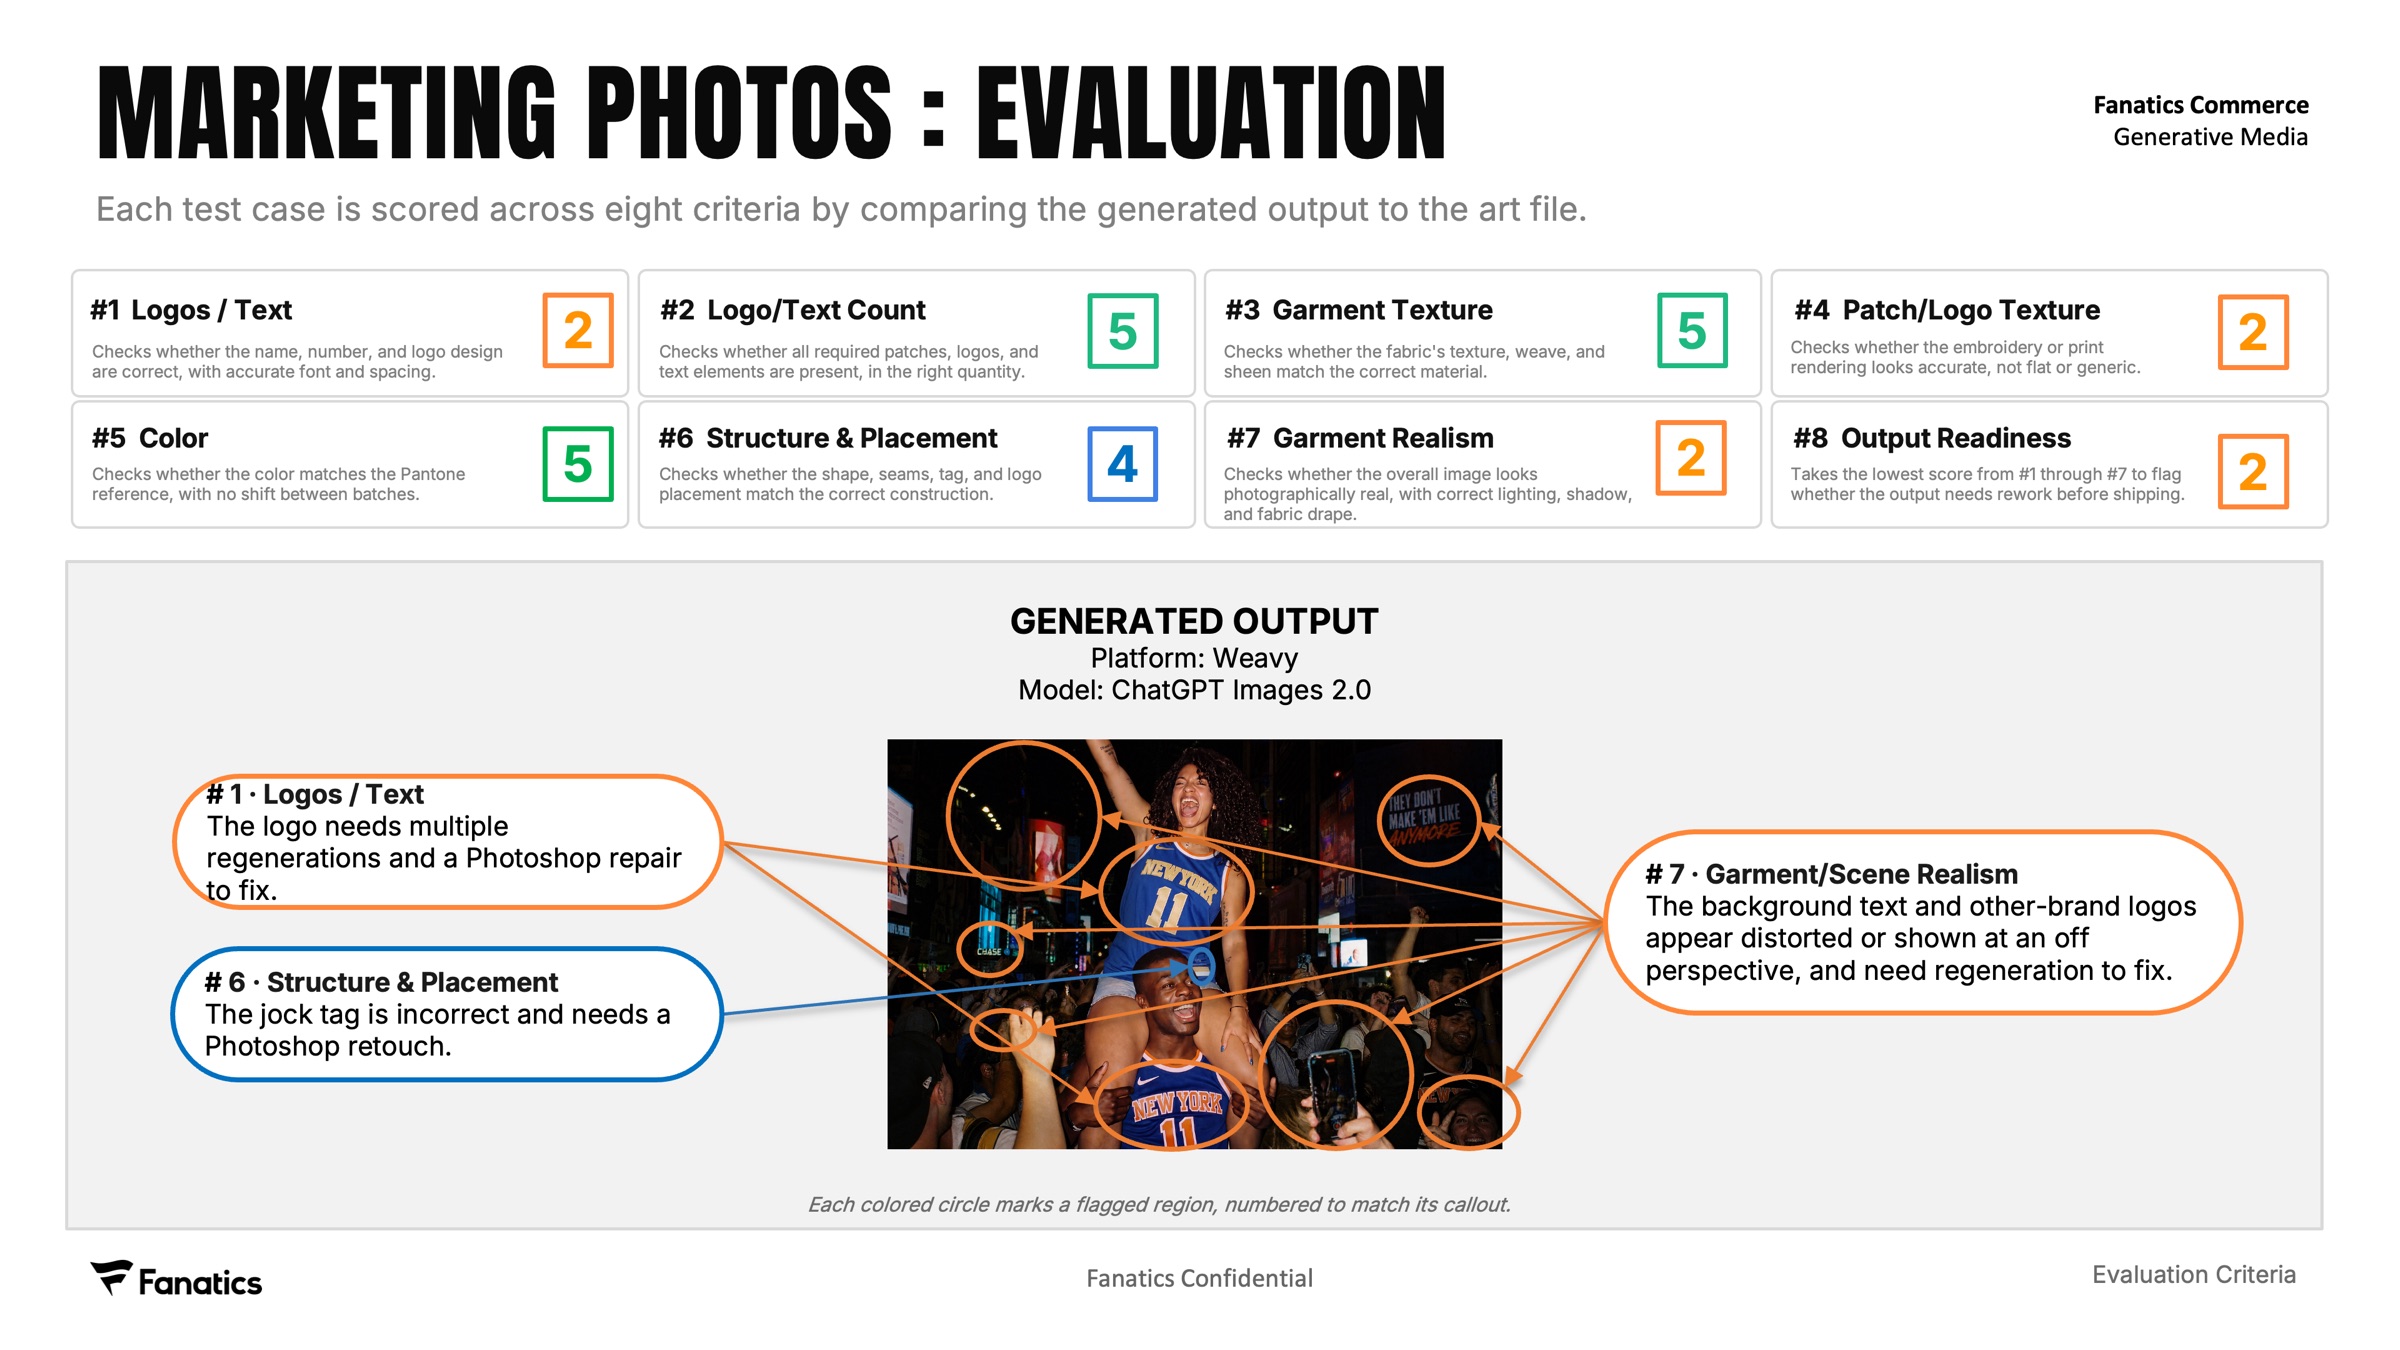
Each output is scored against the art file, with flagged regions numbered to the criterion they fail and a note on how each was fixed.
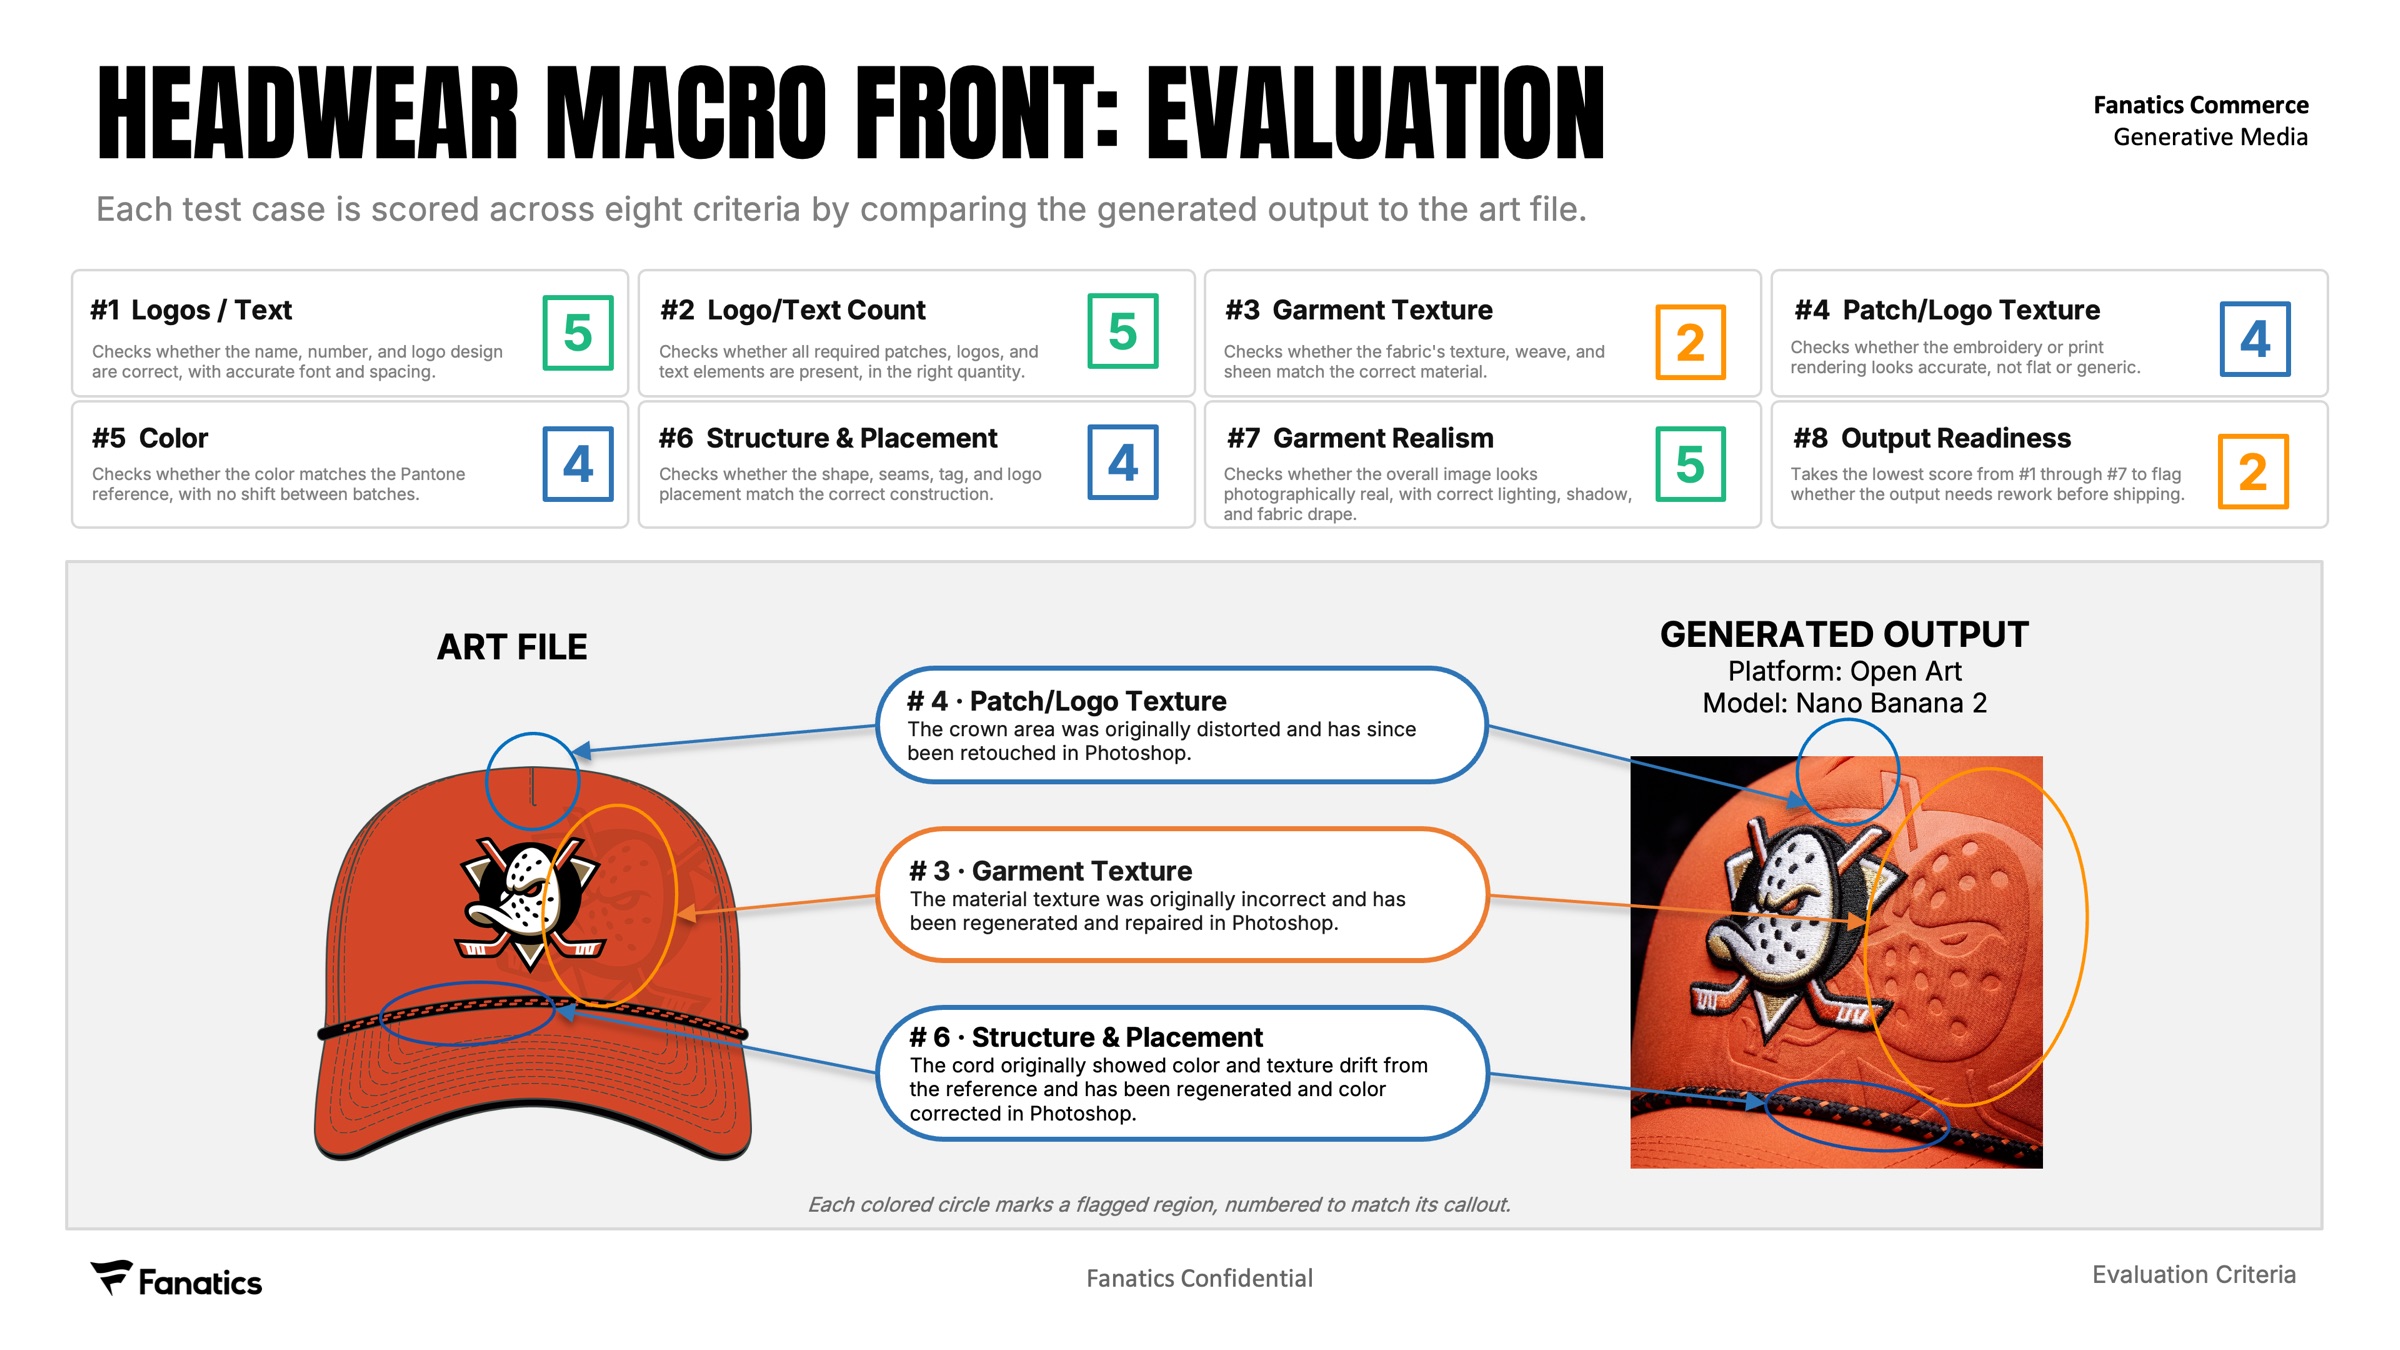
Insights
- Hollow-body swaps passed every criterion: the garment image carries its own graphics, so there is little for the model to invent.
- Type is the weakest point. Numerals, wordmarks and small text such as jock tags usually need several regenerations or a Photoshop fix.
- Models add detail that isn't there, such as extra sleeve logos, seams and panels, so absence has to be checked as carefully as presence.
- Construction details like snap counts drift between runs, and color often needs a manual correction.
- Scoring readiness by the lowest criterion keeps a single blocking flaw from hiding behind otherwise strong results.
Impact
The benchmark gives the team a shared bar for adopting new models and platforms. Evaluating a new release now means re-running two steps instead of starting over, and the same high-risk zones guide everyday review of production work.